• bitcoinBitcoin(BTC)$80,382.004.53%
  • ethereumEthereum(ETH)$2,414.446.76%
  • tetherTether(USDT)$1.000.04%
  • binancecoinBNB(BNB)$715.743.23%
  • rippleXRP(XRP)$1.303.90%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$95.644.14%
  • tronTRON(TRX)$0.319576-0.80%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.051.54%
  • zcashZcash(ZEC)$1,292.427.80%
  • HyperliquidHyperliquid(HYPE)$84.101.24%
  • dogecoinDogecoin(DOGE)$0.0767803.70%
  • moneroMonero(XMR)$634.771.79%
  • USDSUSDS(USDS)$1.000.02%
  • whitebitWhiteBIT Coin(WBT)$77.725.17%
  • chainlinkChainlink(LINK)$11.395.02%
  • leo-tokenLEO Token(LEO)$9.340.37%
  • cardanoCardano(ADA)$0.1959925.09%
  • stellarStellar(XLM)$0.1670304.53%
  • bitcoin-cashBitcoin Cash(BCH)$279.953.46%
  • nearNEAR Protocol(NEAR)$4.016.16%
  • uniswapUniswap(UNI)$7.647.78%
  • daiDai(DAI)$1.000.00%
  • Ethena USDeEthena USDe(USDE)$1.000.06%
  • litecoinLitecoin(LTC)$56.075.27%
  • RainRain(RAIN)$0.005955-8.15%
  • CantonCanton(CC)$0.0994033.25%
  • avalanche-2Avalanche(AVAX)$8.673.66%
  • suiSui(SUI)$0.935.44%
  • USD1USD1(USD1)$1.000.03%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.170.91%
  • tether-goldTether Gold(XAUT)$4,080.773.53%
  • hedera-hashgraphHedera(HBAR)$0.0721705.42%
  • quant-networkQuant(QNT)$202.006.40%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • shiba-inuShiba Inu(SHIB)$0.0000053.63%
  • BittensorBittensor(TAO)$234.975.92%
  • paypal-usdPayPal USD(PYUSD)$1.000.02%
  • crypto-com-chainCronos(CRO)$0.0519944.65%
  • Ripple USDRipple USD(RLUSD)$1.000.02%
  • EthenaEthena(ENA)$0.1812916.67%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.03%
  • okbOKB(OKB)$110.353.38%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • pepePepe(PEPE)$0.0000054.09%
  • aaveAave(AAVE)$130.724.33%
  • OndoOndo(ONDO)$0.4070306.31%
  • Pump.funPump.fun(PUMP)$0.0042630.64%
  • MemeCoreMemeCore(M)$0.83-3.77%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Can Language Models Solve Olympiad Programming? Researchers at Princeton University Introduce USACO Benchmark for Rigorously Evaluating Code Language Models

April 20, 2024
in AI & Technology
Reading Time: 4 mins read
A A
Can Language Models Solve Olympiad Programming? Researchers at Princeton University Introduce USACO Benchmark for Rigorously Evaluating Code Language Models
ShareShareShareShareShare

Code generation has emerged as a significant area for evaluating and deploying Large Language Models (LLMs). However, many of the current coding benchmarks, like HumanEval and MBPP, have achieved solution rates above 90% as language models have grown in size and new inference techniques have been created. This saturation points to the need for more difficult benchmarks that can highlight the limitations of existing models and inference techniques while also offering suggestions for improving the capacity of these models for algorithmic reasoning.

Competitive programming offers itself a good path to pursue in this regard. It is intended to objectively evaluate both the development of unique algorithms and human reasoning in challenging situations. There hasn’t been enough problem diversity, in-depth problem analyses, or comprehensive unit test suites in competitive programming evaluation to properly assess algorithmic reasoning abilities.

In response to these constraints, USACO, a constructed coding benchmark with 307 difficult tasks drawn from previous USA Computing Olympiad contests, has been presented by a team of researchers. Each challenge includes an example input-output tuple and an explanation, along with a task within a hypothetical setting. It takes a wide range of algorithmic, mathematical, and common sense expertise, as well as innovative and well-founded thinking, to solve these challenges. 

In contrast to earlier benchmarks that concentrated on program synthesis, models must be able to reason across a variety of settings and create original algorithms specific to each challenge scenario in order to succeed in USACO. Using zero-shot chain-of-thought prompting on USACO, even the most sophisticated language model, GPT-4, only manages an 8.7% zero-shot pass rate@1.

For each challenge, the benchmark also provides official analyses, reference code solutions, high-quality unit tests, and instructional materials similar to competition programming textbooks, with the goal of facilitating the investigation of more inference techniques for competitive programming. A variety of baseline techniques based on self-reflection, retrieval, and their combinations have been created using these resources. Retrieval strategies combined with self-reflection are found to greatly improve performance, more than tripling the zero-shot solve rate of GPT-4. All approaches, meanwhile, are still unable to solve the benchmark above the easiest level, the bronze difficulty tier.

A human-in-the-loop study has also been used to obtain deeper insights into the remaining issues. It has been found that giving GPT-4 tailored suggestions makes it solve 13 out of 15 previously unsolvable problems, outperforming all previous models and methods examined.

The team has summarized their primary contributions as follows.

  1. The USACO benchmark has been introduced. It is the first benchmark to be created from Olympiad programming and includes carefully selected test cases, problem analysis, and additional resources to enable thorough assessment.
  1. LLM inference techniques have been built and analyzed specifically for Olympiad programming challenges. Experimental results have demonstrated that while a combination of these approaches shows promise in improving performance, there is still a large gap in answering the benchmark completely. Examples of these techniques include retrieval and self-reflection.
  1. In contrast to automated tests that only consider execution success, the new study evaluates the potentials and constraints of LLMs for Olympiad programming. This research reveals that only a subset of models can integrate feedback efficiently, providing insight into hidden differences between models when it comes to addressing interactive problem-solving situations.

Check out the Paper and Github. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 40k+ ML SubReddit


For Content Partnership, Please Fill Out This Form Here..


YOU MAY ALSO LIKE

Snap Has More Than 30 Million Paid Subscribers Across Snapchat+ And Other Plans

Atmospheric AI Secures $10M Seed for Procurement Modeling Push – Unite.AI

Tanya Malhotra is a final year undergrad from the University of Petroleum & Energy Studies, Dehradun, pursuing BTech in Computer Science Engineering with a specialization in Artificial Intelligence and Machine Learning.
She is a Data Science enthusiast with good analytical and critical thinking, along with an ardent interest in acquiring new skills, leading groups, and managing work in an organized manner.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

Snap Has More Than 30 Million Paid Subscribers Across Snapchat+ And Other Plans
AI & Technology

Snap Has More Than 30 Million Paid Subscribers Across Snapchat+ And Other Plans

November 4, 2026
Atmospheric AI Secures M Seed for Procurement Modeling Push – Unite.AI
AI & Technology

Atmospheric AI Secures $10M Seed for Procurement Modeling Push – Unite.AI

November 4, 2026
Perplexity Adds Live Web Grounding to Its Decisions API – Unite.AI
AI & Technology

Perplexity Adds Live Web Grounding to Its Decisions API – Unite.AI

November 4, 2026
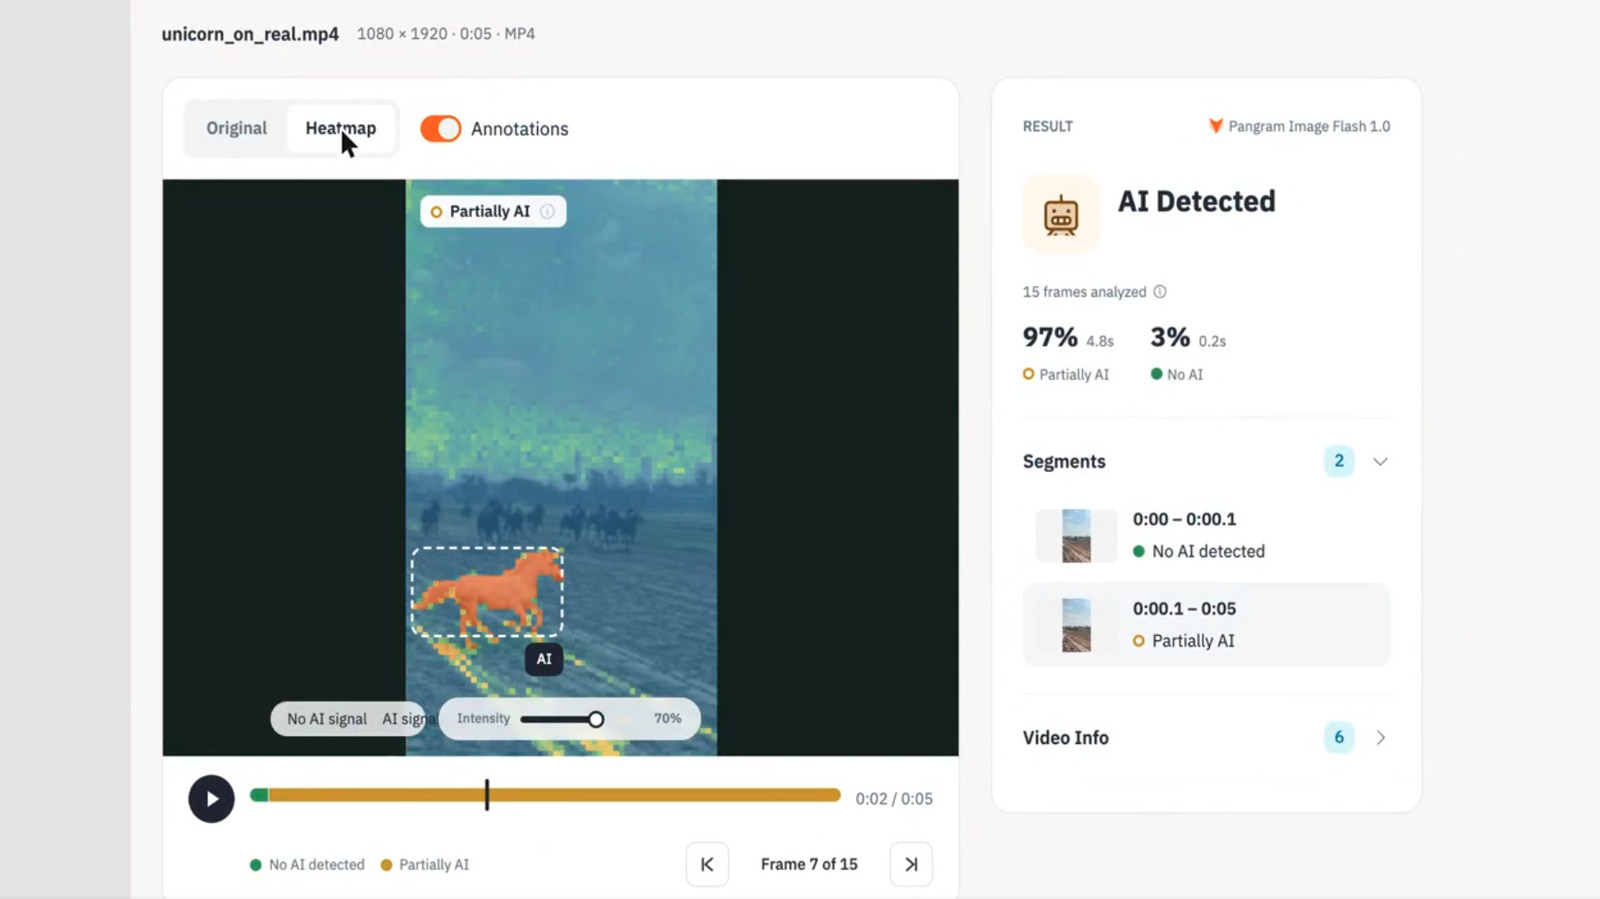
Pangram Expands Its AI Detection Tools To Video And Images
AI & Technology

Pangram Expands Its AI Detection Tools To Video And Images

November 4, 2026
Next Post
In The Long-Term, Owning Is Always Better Than Renting

In The Long-Term, Owning Is Always Better Than Renting

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Anthropic’s S-1 Reveals Financial War Chest

Anthropic’s S-1 Reveals Financial War Chest

October 29, 2026
Agility Robotics Expects 5M Gross Capital Raise Ahead of SPAC Closing – Unite.AI

Agility Robotics Expects $465M Gross Capital Raise Ahead of SPAC Closing – Unite.AI

October 30, 2026
So… this was supposed to save the planet?

So… this was supposed to save the planet?

October 31, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!