• bitcoinBitcoin(BTC)$80,488.004.30%
  • ethereumEthereum(ETH)$2,419.356.46%
  • tetherTether(USDT)$1.000.05%
  • binancecoinBNB(BNB)$718.403.26%
  • rippleXRP(XRP)$1.303.41%
  • usd-coinUSDC(USDC)$1.000.02%
  • solanaSolana(SOL)$95.763.64%
  • tronTRON(TRX)$0.319328-0.89%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.051.53%
  • zcashZcash(ZEC)$1,289.616.00%
  • HyperliquidHyperliquid(HYPE)$84.210.31%
  • dogecoinDogecoin(DOGE)$0.0768993.14%
  • moneroMonero(XMR)$638.741.64%
  • USDSUSDS(USDS)$1.000.02%
  • whitebitWhiteBIT Coin(WBT)$77.864.95%
  • chainlinkChainlink(LINK)$11.394.39%
  • leo-tokenLEO Token(LEO)$9.340.39%
  • cardanoCardano(ADA)$0.1965884.38%
  • stellarStellar(XLM)$0.1675014.28%
  • bitcoin-cashBitcoin Cash(BCH)$280.502.62%
  • nearNEAR Protocol(NEAR)$4.004.51%
  • uniswapUniswap(UNI)$7.666.79%
  • daiDai(DAI)$1.000.02%
  • Ethena USDeEthena USDe(USDE)$1.000.06%
  • litecoinLitecoin(LTC)$56.184.66%
  • RainRain(RAIN)$0.005969-9.55%
  • CantonCanton(CC)$0.0990623.05%
  • avalanche-2Avalanche(AVAX)$8.733.48%
  • suiSui(SUI)$0.934.91%
  • USD1USD1(USD1)$1.000.06%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.170.11%
  • tether-goldTether Gold(XAUT)$4,071.763.66%
  • hedera-hashgraphHedera(HBAR)$0.0724865.16%
  • quant-networkQuant(QNT)$202.986.30%
  • Global DollarGlobal Dollar(USDG)$1.000.02%
  • shiba-inuShiba Inu(SHIB)$0.0000053.20%
  • BittensorBittensor(TAO)$235.775.28%
  • paypal-usdPayPal USD(PYUSD)$1.000.02%
  • crypto-com-chainCronos(CRO)$0.0519804.17%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • EthenaEthena(ENA)$0.1806505.45%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.14%
  • okbOKB(OKB)$110.823.30%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • pepePepe(PEPE)$0.0000051.81%
  • aaveAave(AAVE)$131.684.59%
  • OndoOndo(ONDO)$0.4084476.02%
  • Pump.funPump.fun(PUMP)$0.004281-0.33%
  • MemeCoreMemeCore(M)$0.84-2.33%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Researchers from KAUST and Harvard Introduce MiniGPT4-Video: A Multimodal Large Language Model (LLM) Designed Specifically for Video Understanding

April 9, 2024
in AI & Technology
Reading Time: 4 mins read
A A
Researchers from KAUST and Harvard Introduce MiniGPT4-Video: A Multimodal Large Language Model (LLM) Designed Specifically for Video Understanding
ShareShareShareShareShare

In the rapidly evolving digital communication landscape, integrating visual and textual data for enhanced video understanding has emerged as a critical area of research. Large Language Models (LLMs) have demonstrated unparalleled capabilities in processing and generating text, transforming how to interact with digital content. However, these models have primarily been text-centric, leaving a significant gap in their ability to comprehend and interact with the more complex and dynamic medium of video.

Unlike static images, videos offer a rich tapestry of temporal visual data coupled with textual information, such as subtitles or conversations. This combination presents a unique challenge: designing models to process this multimodal data and understand the nuanced interplay between visual scenes and accompanying text. Traditional methods have made strides in this direction, yet they often fall short of capturing the full depth of videos, leading to a loss of critical information. Approaches like spatial pooling and simplistic tokenization have been unable to fully leverage the temporal dynamics intrinsic to video data fully, underscoring the need for more advanced solutions.

KAUST and Harvard University researchers present MiniGPT4-Video, a pioneering multimodal LLM tailored specifically for video understanding. Expanding on the success of MiniGPT-v2, which revolutionized the translation of visual features into actionable insights for static images, MiniGPT4-Video takes this innovation to the realm of video. By processing visual and textual data sequences, the model achieves a deeper comprehension of videos, surpassing existing state-of-the-art methods in interpreting complex multimodal content.

MiniGPT4-Video distinguishes itself through its innovative approach to handling multimodal inputs. The model reduces information loss by concatenating every four adjacent visual tokens, effectively lowering the token count while preserving essential visual details. It then enriches this visual representation with textual data, incorporating subtitles for each frame. This method allows MiniGPT4-Video to process visual and textual elements concurrently, providing a comprehensive understanding of video content. The model’s performance is noteworthy, demonstrating significant improvements across several benchmarks, including MSVD, MSRVTT, TGIF, and TVQA. Specifically, it registered gains of 4.22%, 1.13%, 20.82%, and 13.1% on these benchmarks, respectively.

One of the most compelling aspects of MiniGPT4-Video is its utilization of subtitles as input. This inclusion has proven beneficial in contexts where textual information complements visual data. For example, in the TVQA benchmark, the integration of subtitles led to a remarkable increase in accuracy, from 33.9% to 54.21%, underscoring the value of combining visual and textual data for enhanced video understanding. However, it’s also worth noting that for datasets primarily focused on visual questions, the addition of subtitles did not significantly impact performance, indicating the model’s versatility and adaptability to different types of video content.
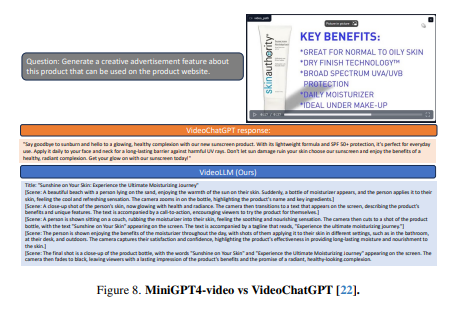
In conclusion, MiniGPT4-Video offers a robust solution that adeptly navigates the complexities of integrating visual and textual data. By directly inputting both types of data, the model achieves a higher level of comprehension and sets a new benchmark for future research in multimodal content analysis. Its impressive performance across diverse benchmarks demonstrates its potential to revolutionize how to interact with, interpret, and leverage video content in various applications. As the digital landscape continues to evolve, models like MiniGPT4-Video pave the way for more nuanced and comprehensive approaches to understanding video’s rich, multimodal world.


Check out the Paper and Project. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 40k+ ML SubReddit

YOU MAY ALSO LIKE

Snap Has More Than 30 Million Paid Subscribers Across Snapchat+ And Other Plans

Atmospheric AI Secures $10M Seed for Procurement Modeling Push – Unite.AI

Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

Snap Has More Than 30 Million Paid Subscribers Across Snapchat+ And Other Plans
AI & Technology

Snap Has More Than 30 Million Paid Subscribers Across Snapchat+ And Other Plans

November 4, 2026
Atmospheric AI Secures M Seed for Procurement Modeling Push – Unite.AI
AI & Technology

Atmospheric AI Secures $10M Seed for Procurement Modeling Push – Unite.AI

November 4, 2026
Perplexity Adds Live Web Grounding to Its Decisions API – Unite.AI
AI & Technology

Perplexity Adds Live Web Grounding to Its Decisions API – Unite.AI

November 4, 2026
Pangram Expands Its AI Detection Tools To Video And Images
AI & Technology

Pangram Expands Its AI Detection Tools To Video And Images

November 4, 2026
Next Post
Two people killed, at least 10 injured in school bus crash

Two people killed, at least 10 injured in school bus crash

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
When a humanoid and a drone become besties

When a humanoid and a drone become besties

October 30, 2026
U.S. military carries out limited strikes on Iran’s Qeshm Island, U.S. officials say – NBC News

U.S. military carries out limited strikes on Iran’s Qeshm Island, U.S. officials say – NBC News

November 3, 2026
Post Game: History doesn’t repeat itself but ‘it feels awfully a lot like 2006’

Post Game: History doesn’t repeat itself but ‘it feels awfully a lot like 2006’

November 1, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!