• bitcoinBitcoin(BTC)$77,907.00-0.16%
  • ethereumEthereum(ETH)$2,285.040.61%
  • tetherTether(USDT)$1.00-0.05%
  • binancecoinBNB(BNB)$706.00-1.08%
  • rippleXRP(XRP)$1.25-0.72%
  • usd-coinUSDC(USDC)$1.00-0.04%
  • solanaSolana(SOL)$94.04-1.52%
  • tronTRON(TRX)$0.3161351.92%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.080.00%
  • zcashZcash(ZEC)$1,247.810.08%
  • HyperliquidHyperliquid(HYPE)$85.64-2.74%
  • dogecoinDogecoin(DOGE)$0.075230-0.79%
  • moneroMonero(XMR)$608.320.48%
  • USDSUSDS(USDS)$1.00-0.04%
  • whitebitWhiteBIT Coin(WBT)$74.90-0.05%
  • leo-tokenLEO Token(LEO)$9.400.00%
  • chainlinkChainlink(LINK)$11.25-3.98%
  • cardanoCardano(ADA)$0.190515-1.85%
  • stellarStellar(XLM)$0.167134-0.99%
  • bitcoin-cashBitcoin Cash(BCH)$276.05-2.55%
  • nearNEAR Protocol(NEAR)$4.11-6.92%
  • daiDai(DAI)$1.00-0.06%
  • Ethena USDeEthena USDe(USDE)$1.00-0.05%
  • uniswapUniswap(UNI)$7.20-0.98%
  • RainRain(RAIN)$0.0061953.93%
  • litecoinLitecoin(LTC)$54.88-2.07%
  • USD1USD1(USD1)$1.00-0.04%
  • avalanche-2Avalanche(AVAX)$8.54-3.25%
  • CantonCanton(CC)$0.094619-2.73%
  • suiSui(SUI)$0.88-2.42%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.20-2.38%
  • tether-goldTether Gold(XAUT)$3,888.570.41%
  • hedera-hashgraphHedera(HBAR)$0.070889-1.28%
  • Global DollarGlobal Dollar(USDG)$1.00-0.04%
  • quant-networkQuant(QNT)$197.33-1.02%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • shiba-inuShiba Inu(SHIB)$0.000005-1.51%
  • BittensorBittensor(TAO)$229.40-3.41%
  • crypto-com-chainCronos(CRO)$0.050810-1.61%
  • Ripple USDRipple USD(RLUSD)$1.00-0.04%
  • EthenaEthena(ENA)$0.178988-4.55%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.16%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • okbOKB(OKB)$112.120.64%
  • pepePepe(PEPE)$0.000005-2.43%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • aaveAave(AAVE)$131.08-4.06%
  • MemeCoreMemeCore(M)$0.85-0.25%
  • OndoOndo(ONDO)$0.393585-4.29%
  • Pump.funPump.fun(PUMP)$0.004079-4.26%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Linear Attention Sequence Parallel (LASP): An Efficient Machine Learning Method Tailored to Linear Attention-Based Language Models

April 7, 2024
in AI & Technology
Reading Time: 4 mins read
A A
Linear Attention Sequence Parallel (LASP): An Efficient Machine Learning Method Tailored to Linear Attention-Based Language Models
ShareShareShareShareShare

Linear attention-based models are gaining attention for their faster processing speed and comparable performance to Softmax transformers. However, large language models (LLMs), due to their large size and longer sequence lengths, exert significant strain on contemporary GPU hardware because a single GPU’s memory confines a language model’s maximum sequence length.

Sequence Parallelism (SP) techniques are often utilized to divide a long sequence into several sub-sequences and train them on multiple GPUs separately. However, current SP methods underutilize linear attention features, resulting in inefficient parallelism and usability issues. 

Researchers from Shanghai AI Laboratory and TapTap present the linear attention sequence parallel (LASP) technique, which optimizes sequence parallelism on linear transformers. It employs point-to-point (P2P) communication for efficient state exchange among GPUs within or across nodes. LASP maximizes the use of right-product kernel tricks in linear attention. Importantly, it doesn’t rely on attention head partitioning, making it adaptable to multi-head, multi-query, and grouped-query attentions.

LASP employs a tiling approach to partition input sequences into sub-sequence chunks distributed across GPUs. It distinguishes attention computation into intra-chunks and inter-chunks for utilizing linear attention’s right-product advantage. Intra-chunks use conventional attention computation, while inter-chunks exploit kernel tricks. The method also includes data distribution, forward pass, and backward pass mechanisms to enhance parallel processing efficiency.

LASP achieves significant throughput enhancement for linear attention through efficient communication design, surpassing DeepSpeed-Ulysses by 38% and Megatron by 136% in throughput at 256K sequence length on 1B model. Moreover, LASP, with system optimizations like kernel fusion and KV State caching, supports longer sequence lengths within the same cluster, reaching 2048K for the 1B model and 512K for the 7B model.

Key contributions of this research are as follows: 

  • A new SP strategy tailored to linear attention: Enabling linear attention-based models to scale for long sequences without being limited by a single GPU. 
  • Sequence length-independent communication over-head: Their elegant communication mechanism harnesses the right-product kernel trick of linear attention to ensure that the exchanging of linear attention intermediate states is sequence length-independent.
  • GPU-friendly implementation: Optimized LASP’s execution on GPUs through meticulous system engineering, including kernel fusion and KV State caching.
  • Data-parallel compatibility: LASP is compatible with all batch-level DDP methods, such as PyTorch/Legacy DDP, FSDP, and ZeRO-series optimizers.

In conclusion,  LASP is introduced to overcome the limitations of existing SP methods on linear transformers by leveraging linear attention features to enhance parallelism efficiency and usability. Implementing P2P communication, kernel fusion, and KV state caching reduces communication traffic and improves GPU cluster utilization. Compatibility with batch-level DDP methods ensures practicality for large-scale distributed training. Experiments highlight LASP’s advantages in scalability, speed, memory usage, and convergence performance compared to existing SP methods.


Check out the Paper and Github. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 39k+ ML SubReddit

YOU MAY ALSO LIKE

Marble Cognition Raises $3.75M Pre-Seed to Build AI Coworkers That Learn by Observing – Unite.AI

OpenAI Sets Shared ChatGPT and Codex Usage Allowance for December – Unite.AI

Asjad is an intern consultant at Marktechpost. He is persuing B.Tech in mechanical engineering at the Indian Institute of Technology, Kharagpur. Asjad is a Machine learning and deep learning enthusiast who is always researching the applications of machine learning in healthcare.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

Marble Cognition Raises .75M Pre-Seed to Build AI Coworkers That Learn by Observing – Unite.AI
AI & Technology

Marble Cognition Raises $3.75M Pre-Seed to Build AI Coworkers That Learn by Observing – Unite.AI

November 2, 2026
OpenAI Sets Shared ChatGPT and Codex Usage Allowance for December – Unite.AI
AI & Technology

OpenAI Sets Shared ChatGPT and Codex Usage Allowance for December – Unite.AI

November 2, 2026
How Long Is A New Apple TV Actually Supposed To Last?
AI & Technology

How Long Is A New Apple TV Actually Supposed To Last?

November 2, 2026
6 Google Maps Features That Work Better On Android Auto Vs. CarPlay
AI & Technology

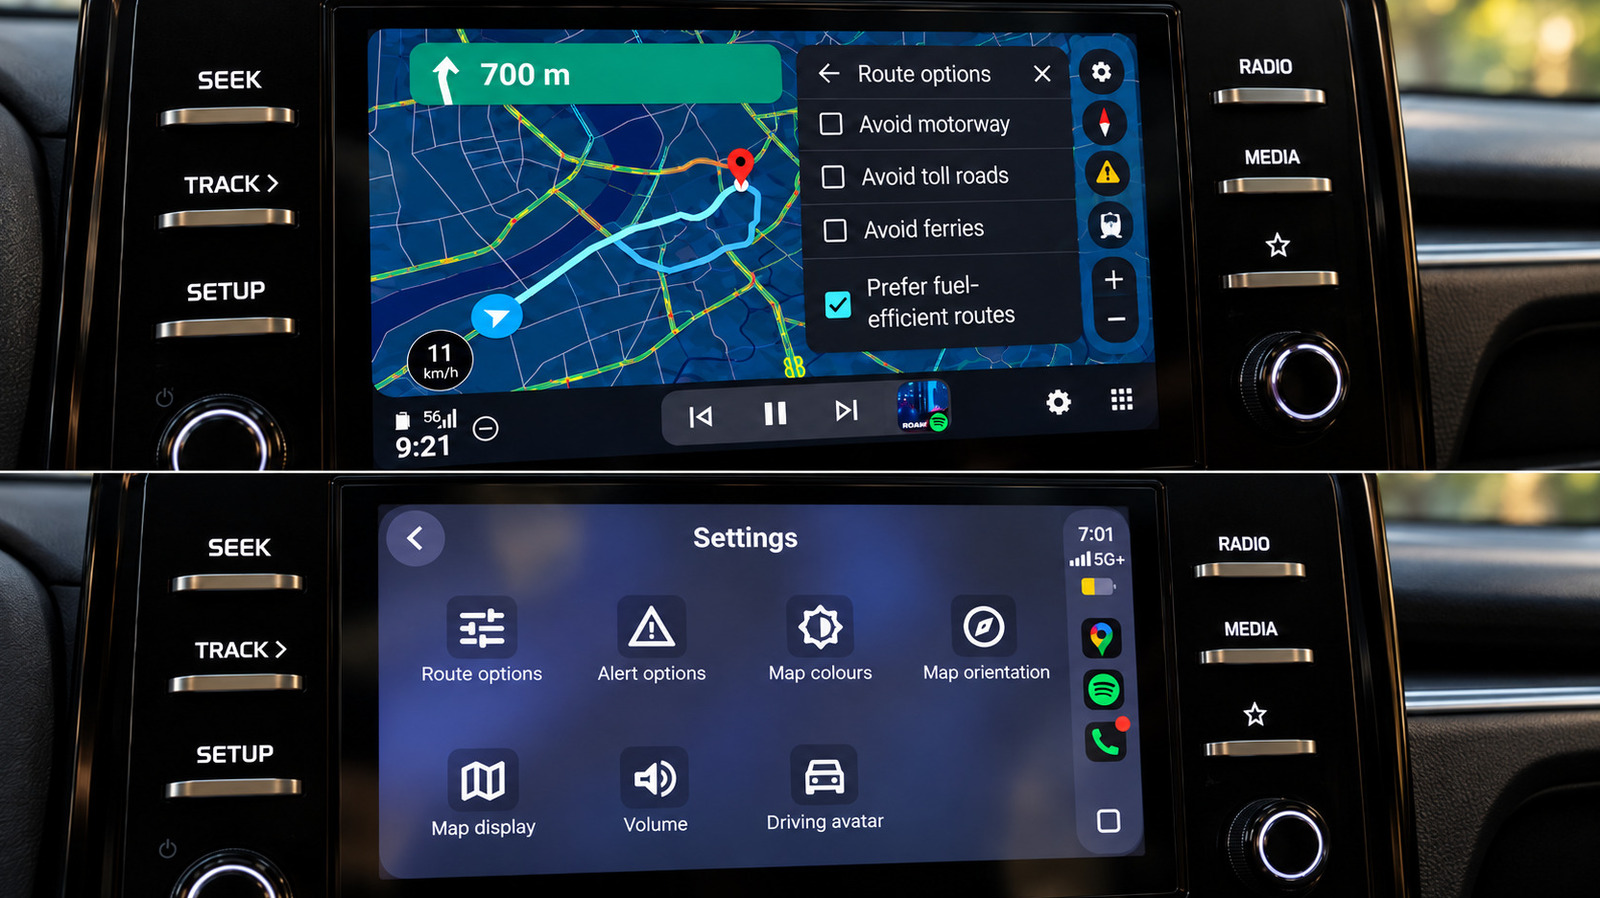
6 Google Maps Features That Work Better On Android Auto Vs. CarPlay

November 2, 2026
Next Post
Jobs Data and Apple Layoffs | Bloomberg Technology

Jobs Data and Apple Layoffs | Bloomberg Technology

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
New video of deadly school bus crash

New video of deadly school bus crash

October 30, 2026
Apple Adds More Siri AI Tools In Its 27.2 System Updates, Out Today

Apple Adds More Siri AI Tools In Its 27.2 System Updates, Out Today

October 26, 2026
Democrats ‘heartened’ by Republicans pouring money and playing defense in deep red states

Democrats ‘heartened’ by Republicans pouring money and playing defense in deep red states

October 31, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!