• bitcoinBitcoin(BTC)$75,520.00-4.12%
  • ethereumEthereum(ETH)$2,395.24-5.96%
  • tetherTether(USDT)$1.00-0.04%
  • binancecoinBNB(BNB)$712.04-1.58%
  • rippleXRP(XRP)$1.28-11.25%
  • usd-coinUSDC(USDC)$1.00-0.02%
  • solanaSolana(SOL)$96.72-6.29%
  • tronTRON(TRX)$0.332433-1.97%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.01-2.76%
  • zcashZcash(ZEC)$1,110.83-5.71%
  • HyperliquidHyperliquid(HYPE)$76.61-4.99%
  • dogecoinDogecoin(DOGE)$0.079789-5.48%
  • RainRain(RAIN)$0.014077-1.79%
  • USDSUSDS(USDS)$1.00-0.03%
  • moneroMonero(XMR)$500.85-2.69%
  • whitebitWhiteBIT Coin(WBT)$77.68-4.80%
  • leo-tokenLEO Token(LEO)$8.88-1.32%
  • chainlinkChainlink(LINK)$10.90-6.34%
  • cardanoCardano(ADA)$0.194708-7.60%
  • stellarStellar(XLM)$0.175335-9.28%
  • Ethena USDeEthena USDe(USDE)$1.00-0.07%
  • daiDai(DAI)$1.000.01%
  • USD1USD1(USD1)$1.00-0.03%
  • bitcoin-cashBitcoin Cash(BCH)$215.08-4.76%
  • litecoinLitecoin(LTC)$51.05-4.28%
  • uniswapUniswap(UNI)$6.24-4.91%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.32-2.66%
  • CantonCanton(CC)$0.090356-7.80%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • hedera-hashgraphHedera(HBAR)$0.074654-4.31%
  • avalanche-2Avalanche(AVAX)$7.26-4.94%
  • nearNEAR Protocol(NEAR)$2.31-7.66%
  • shiba-inuShiba Inu(SHIB)$0.000005-7.23%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.04%
  • suiSui(SUI)$0.68-6.91%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • tether-goldTether Gold(XAUT)$4,291.88-0.23%
  • crypto-com-chainCronos(CRO)$0.054996-7.74%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • MemeCoreMemeCore(M)$1.121.90%
  • BittensorBittensor(TAO)$217.47-7.33%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • okbOKB(OKB)$109.68-3.42%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.03%
  • BitwayBitway(BTW)$0.7017.29%
  • aaveAave(AAVE)$121.24-6.32%
  • pax-goldPAX Gold(PAXG)$4,293.96-0.27%
  • AsterAster(ASTER)$0.68-4.01%
  • World Liberty FinancialWorld Liberty Financial(WLFI)$0.056904-1.29%
  • mantleMantle(MNT)$0.54-6.05%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

CMU Researchers Present FlexLLM: An Artificial Intelligence System that can Serve Inference and Parameter-Efficient Finetuning Requests in the Same Iteration

March 8, 2024
in AI & Technology
Reading Time: 4 mins read
A A
CMU Researchers Present FlexLLM: An Artificial Intelligence System that can Serve Inference and Parameter-Efficient Finetuning Requests in the Same Iteration
ShareShareShareShareShare

In artificial intelligence, the surge in large language model (LLM) development has significantly transformed how machines understand and generate text, mimicking human conversation with remarkable accuracy. These models have become integral to various applications, including but not limited to content creation, automated customer support, and language translation. However, deploying these models in practical scenarios is hindered by their colossal size, often comprising billions of parameters, making their finetuning for specific tasks computationally expensive and technically challenging.

A novel approach has been developed that seeks to refine the finetuning process of LLMs without the need for extensive computational resources. Traditional methods involve updating a substantial portion of the model’s parameters, which demands significant memory and processing power. In contrast, the latest methodologies focus on adjusting only a small subset of parameters, thereby reducing the computational load. This technique, known as parameter-efficient finetuning (PEFT), has paved the way for more practical applications of LLMs by making the finetuning process faster and more accessible.

Carnegie Mellon University and Stanford University researchers have introduced a groundbreaking system named FlexLLM. This system is engineered to streamline the simultaneous handling of LLM inference and PEFT tasks on shared computational resources. FlexLLM leverages the inherent complementary nature of these tasks to optimize resource utilization, showcasing a significant leap in efficiency compared to traditional methods that treat these tasks separately.

FlexLLM’s architecture is underpinned by two core innovations: a token-level finetuning mechanism and a suite of memory optimization strategies. The token-level approach breaks down the finetuning computation into smaller, manageable units, allowing for parallel processing of multiple tasks. This granularity reduces the overall memory footprint required for finetuning and accelerates the adaptation of LLMs to new tasks without compromising performance. Memory optimization further enhances this efficiency by implementing techniques such as graph pruning and dependent parallelization, which minimize the memory overhead associated with maintaining model states during the finetuning process.

As demonstrated in preliminary evaluations, FlexLLM’s performance marks a significant advancement in the field. FlexLLM maintained more than 80% of its peak finetuning throughput in scenarios characterized by heavy inference workloads, a feat that existing systems fail to achieve. This efficiency translates into improved GPU utilization for inference and finetuning tasks, showcasing FlexLLM’s capability to navigate the challenges posed by the resource-intensive nature of LLMs.

FlexLLM not only represents a technical breakthrough in optimizing LLM deployment but also promises to broaden the accessibility and applicability of these models across various domains. By significantly lowering the barriers to fine-tuning LLMs, this system opens up new avenues for innovation and research, enabling more entities to leverage the power of advanced natural language processing technologies.

In conclusion, the development of FlexLLM addresses a critical bottleneck in the deployment of LLMs by offering a more resource-efficient framework for their finetuning and inference tasks. This system enhances computational efficiency and lays the groundwork for the future expansion of LLM applications, making the most of artificial intelligence’s potential to mimic and understand human language. 


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and Google News. Join our 38k+ ML SubReddit, 41k+ Facebook Community, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our Telegram Channel

You may also like our FREE AI Courses….

YOU MAY ALSO LIKE

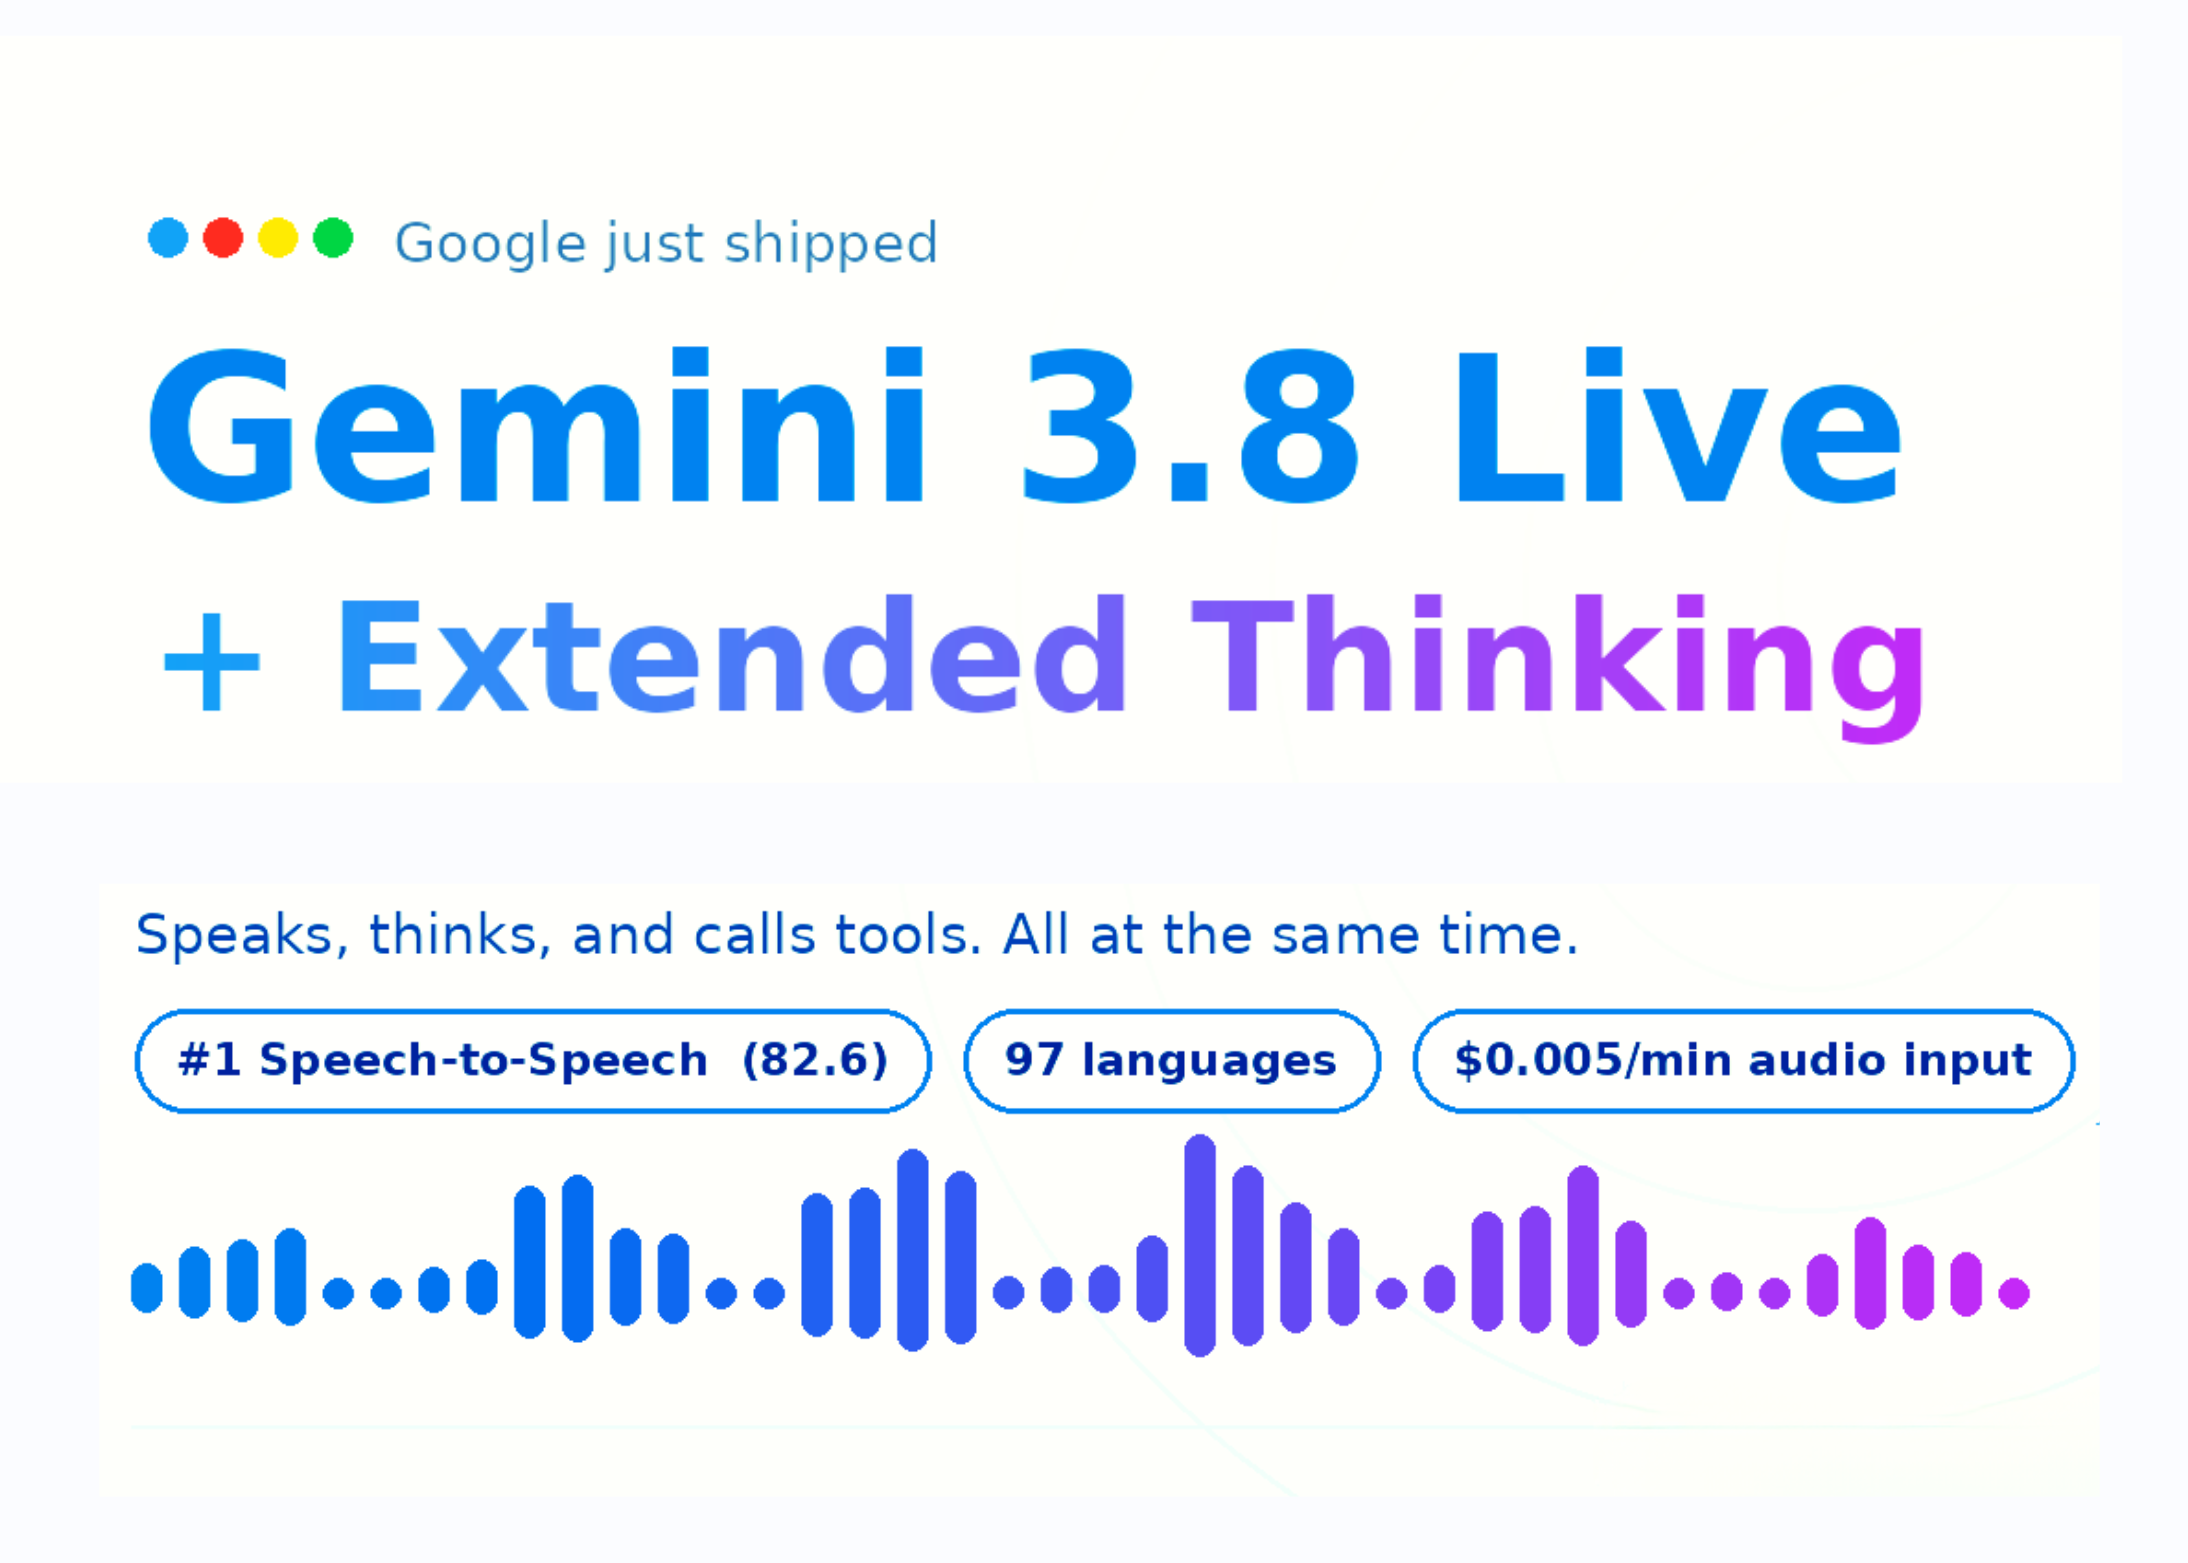
Google Releases Gemini 3.8 Live and 3.8 Live Extended Thinking for Production Grade Voice Agents

How To Improve The Audio Quality On Your iPhone

Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.


🚀 [FREE AI WEBINAR] ‘Building with Google’s New Open Gemma Models’ (March 11, 2024) [Promoted]


Credit: Source link

ShareTweetSendSharePin

Related Posts

Google Releases Gemini 3.8 Live and 3.8 Live Extended Thinking for Production Grade Voice Agents
AI & Technology

Google Releases Gemini 3.8 Live and 3.8 Live Extended Thinking for Production Grade Voice Agents

September 15, 2026
How To Improve The Audio Quality On Your iPhone
AI & Technology

How To Improve The Audio Quality On Your iPhone

September 15, 2026
Ferrovalle Taps INFORM for AI Smart Yard at Mexico City Rail Hub – Unite.AI
AI & Technology

Ferrovalle Taps INFORM for AI Smart Yard at Mexico City Rail Hub – Unite.AI

September 15, 2026
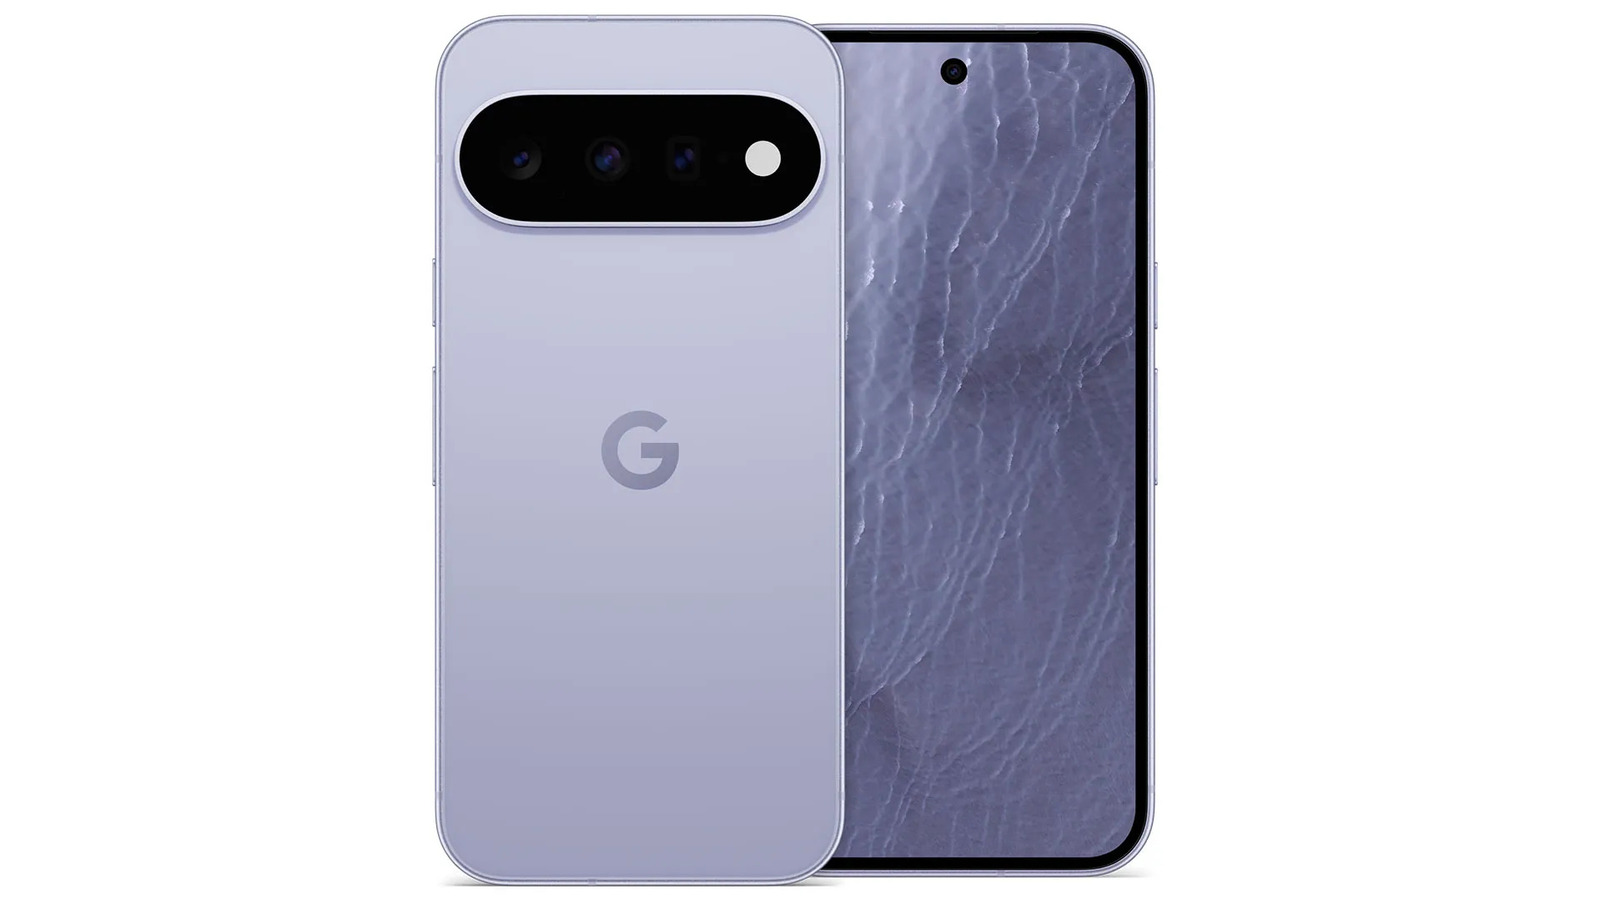
Google’s Latest Pixel Drop Will Keep You More Connected To Your VIPs
AI & Technology

Google’s Latest Pixel Drop Will Keep You More Connected To Your VIPs

September 15, 2026
Next Post
This Morning’s Top Headlines – June 2

This Morning’s Top Headlines – June 2

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
August was joint-hottest month ever recorded globally – theguardian.com

August was joint-hottest month ever recorded globally – theguardian.com

September 10, 2026
Jimmy Kimmel says show won’t air interview with James Talarico on TV, citing FCC threats

Jimmy Kimmel says show won’t air interview with James Talarico on TV, citing FCC threats

September 14, 2026
AI Agents Will Turn Prompting Into a Management Skill – Unite.AI

AI Agents Will Turn Prompting Into a Management Skill – Unite.AI

September 14, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!