• bitcoinBitcoin(BTC)$77,787.000.67%
  • ethereumEthereum(ETH)$2,516.31-0.18%
  • tetherTether(USDT)$1.00-0.02%
  • binancecoinBNB(BNB)$724.18-0.49%
  • rippleXRP(XRP)$1.370.56%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$101.19-0.76%
  • tronTRON(TRX)$0.338825-0.36%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.000.00%
  • zcashZcash(ZEC)$1,109.71-2.11%
  • HyperliquidHyperliquid(HYPE)$79.780.62%
  • dogecoinDogecoin(DOGE)$0.084078-1.02%
  • RainRain(RAIN)$0.015228-3.29%
  • USDSUSDS(USDS)$1.00-0.01%
  • moneroMonero(XMR)$522.86-3.54%
  • whitebitWhiteBIT Coin(WBT)$80.610.53%
  • chainlinkChainlink(LINK)$11.41-0.90%
  • leo-tokenLEO Token(LEO)$9.03-0.32%
  • cardanoCardano(ADA)$0.2079540.20%
  • stellarStellar(XLM)$0.1812290.61%
  • Ethena USDeEthena USDe(USDE)$1.00-0.03%
  • daiDai(DAI)$1.000.00%
  • bitcoin-cashBitcoin Cash(BCH)$224.22-0.44%
  • USD1USD1(USD1)$1.00-0.01%
  • litecoinLitecoin(LTC)$54.481.49%
  • uniswapUniswap(UNI)$6.430.91%
  • CantonCanton(CC)$0.096534-1.08%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.35-1.55%
  • hedera-hashgraphHedera(HBAR)$0.0761391.47%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • avalanche-2Avalanche(AVAX)$7.430.08%
  • nearNEAR Protocol(NEAR)$2.381.30%
  • shiba-inuShiba Inu(SHIB)$0.000005-1.06%
  • suiSui(SUI)$0.72-0.98%
  • crypto-com-chainCronos(CRO)$0.058167-2.83%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • tether-goldTether Gold(XAUT)$4,335.97-0.33%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • MemeCoreMemeCore(M)$1.14-4.21%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • okbOKB(OKB)$114.13-0.34%
  • BittensorBittensor(TAO)$235.380.28%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.13%
  • aaveAave(AAVE)$126.25-0.93%
  • AsterAster(ASTER)$0.700.05%
  • pax-goldPAX Gold(PAXG)$4,338.80-0.39%
  • BitwayBitway(BTW)$0.6824.36%
  • mantleMantle(MNT)$0.560.35%
  • World Liberty FinancialWorld Liberty Financial(WLFI)$0.0569810.04%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Researchers from the University of Washington Introduce Fiddler: A Resource-Efficient Inference Engine for LLMs with CPU-GPU Orchestration

February 27, 2024
in AI & Technology
Reading Time: 5 mins read
A A
Researchers from the University of Washington Introduce Fiddler: A Resource-Efficient Inference Engine for LLMs with CPU-GPU Orchestration
ShareShareShareShareShare

Mixture-of-experts (MoE) models have revolutionized artificial intelligence by enabling the dynamic allocation of tasks to specialized components within larger models. However, a major challenge in adopting MoE models is their deployment in environments with limited computational resources. The vast size of these models often surpasses the memory capabilities of standard GPUs, restricting their use in low-resource settings. This limitation hampers the models’ effectiveness and challenges researchers and developers aiming to leverage MoE models for complex computational tasks without access to high-end hardware.

Existing methods for deploying MoE models in constrained environments typically involve offloading part of the model computation to the CPU. While this approach helps manage GPU memory limitations, it introduces significant latency due to the slow data transfers between the CPU and GPU. State-of-the-art MoE models also often employ alternative activation functions, such as SiLU, which makes it challenging to apply sparsity-exploiting strategies directly. Pruning channels not close enough to zero could negatively impact the model’s performance, requiring a more sophisticated approach to leverage sparsity.

A team of researchers from the University of Washington has introduced Fiddler, an innovative solution designed to optimize the deployment of MoE models by efficiently orchestrating CPU and GPU resources. Fiddler minimizes the data transfer overhead by executing expert layers on the CPU, reducing the latency associated with moving data between CPU and GPU. This approach addresses the limitations of existing methods and enhances the feasibility of deploying large MoE models in resource-constrained environments.
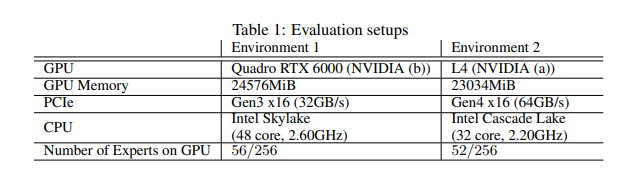
Fiddler distinguishes itself by leveraging the computational capabilities of the CPU for expert layer processing while minimizing the volume of data transferred between the CPU and GPU. This methodology drastically cuts down the latency for CPU-GPU communication, enabling the system to run large MoE models, such as the Mixtral-8x7B with over 90GB of parameters, efficiently on a single GPU with limited memory. Fiddler’s design showcases a significant technical innovation in AI model deployment.
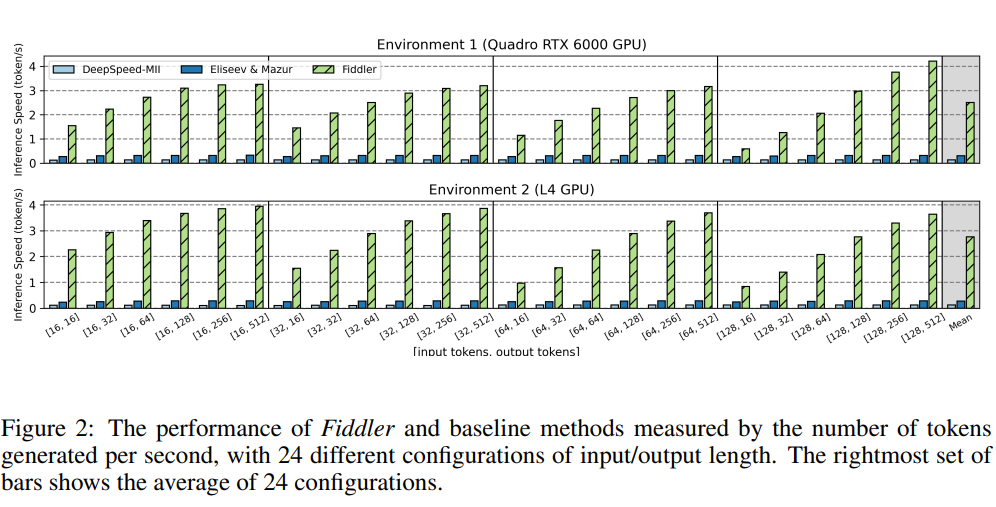
Fiddler’s effectiveness is underscored by its performance metrics, which demonstrate an order of magnitude improvement over traditional offloading methods. The performance is measured by the number of tokens generated per second. Fiddler successfully ran the uncompressed Mixtral-8x7B model in tests, rendering over three tokens per second on a single 24GB GPU. It improves with longer output lengths for the same input length, as the latency of the prefill stage is amortized. On average, Fiddler is faster than Eliseev Mazur by 8.2 times to 10.1 times and quicker than DeepSpeed-MII by 19.4 times to 22.5 times, depending on the environment.

In conclusion, Fiddler represents a significant leap forward in enabling the efficient inference of MoE models in environments with limited computational resources. By ingeniously utilizing CPU and GPU for model inference, Fiddler overcomes the prevalent challenges faced by traditional deployment methods, offering a scalable solution that enhances the accessibility of advanced MoE models. This breakthrough can potentially democratize large-scale AI models, paving the way for broader applications and research in artificial intelligence.


Check out the Paper and Github. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and Google News. Join our 38k+ ML SubReddit, 41k+ Facebook Community, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our Telegram Channel

You may also like our FREE AI Courses….

YOU MAY ALSO LIKE

Anthropic’s 3-Step ‘Pace the Frontier’ Plan Wins OpenAI, xAI and Microsoft Support: Is It Too Late to Slow AI Down?

Which Is Better For Charging Your MacBook?

Nikhil is an intern consultant at Marktechpost. He is pursuing an integrated dual degree in Materials at the Indian Institute of Technology, Kharagpur. Nikhil is an AI/ML enthusiast who is always researching applications in fields like biomaterials and biomedical science. With a strong background in Material Science, he is exploring new advancements and creating opportunities to contribute.


🚀 LLMWare Launches SLIMs: Small Specialized Function-Calling Models for Multi-Step Automation [Check out all the models]


Credit: Source link

ShareTweetSendSharePin

Related Posts

Anthropic’s 3-Step ‘Pace the Frontier’ Plan Wins OpenAI, xAI and Microsoft Support: Is It Too Late to Slow AI Down?
AI & Technology

Anthropic’s 3-Step ‘Pace the Frontier’ Plan Wins OpenAI, xAI and Microsoft Support: Is It Too Late to Slow AI Down?

September 14, 2026
Which Is Better For Charging Your MacBook?
AI & Technology

Which Is Better For Charging Your MacBook?

September 14, 2026
At What Length Do Ethernet Cables Drop To Lower Speeds?
AI & Technology

At What Length Do Ethernet Cables Drop To Lower Speeds?

September 14, 2026
Nadella Announces Public Consultation on Microsoft’s MAI Model Rules – Unite.AI
AI & Technology

Nadella Announces Public Consultation on Microsoft’s MAI Model Rules – Unite.AI

September 13, 2026
Next Post
PlayMakers raises .5M for user-generated content for games

PlayMakers raises $1.5M for user-generated content for games

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
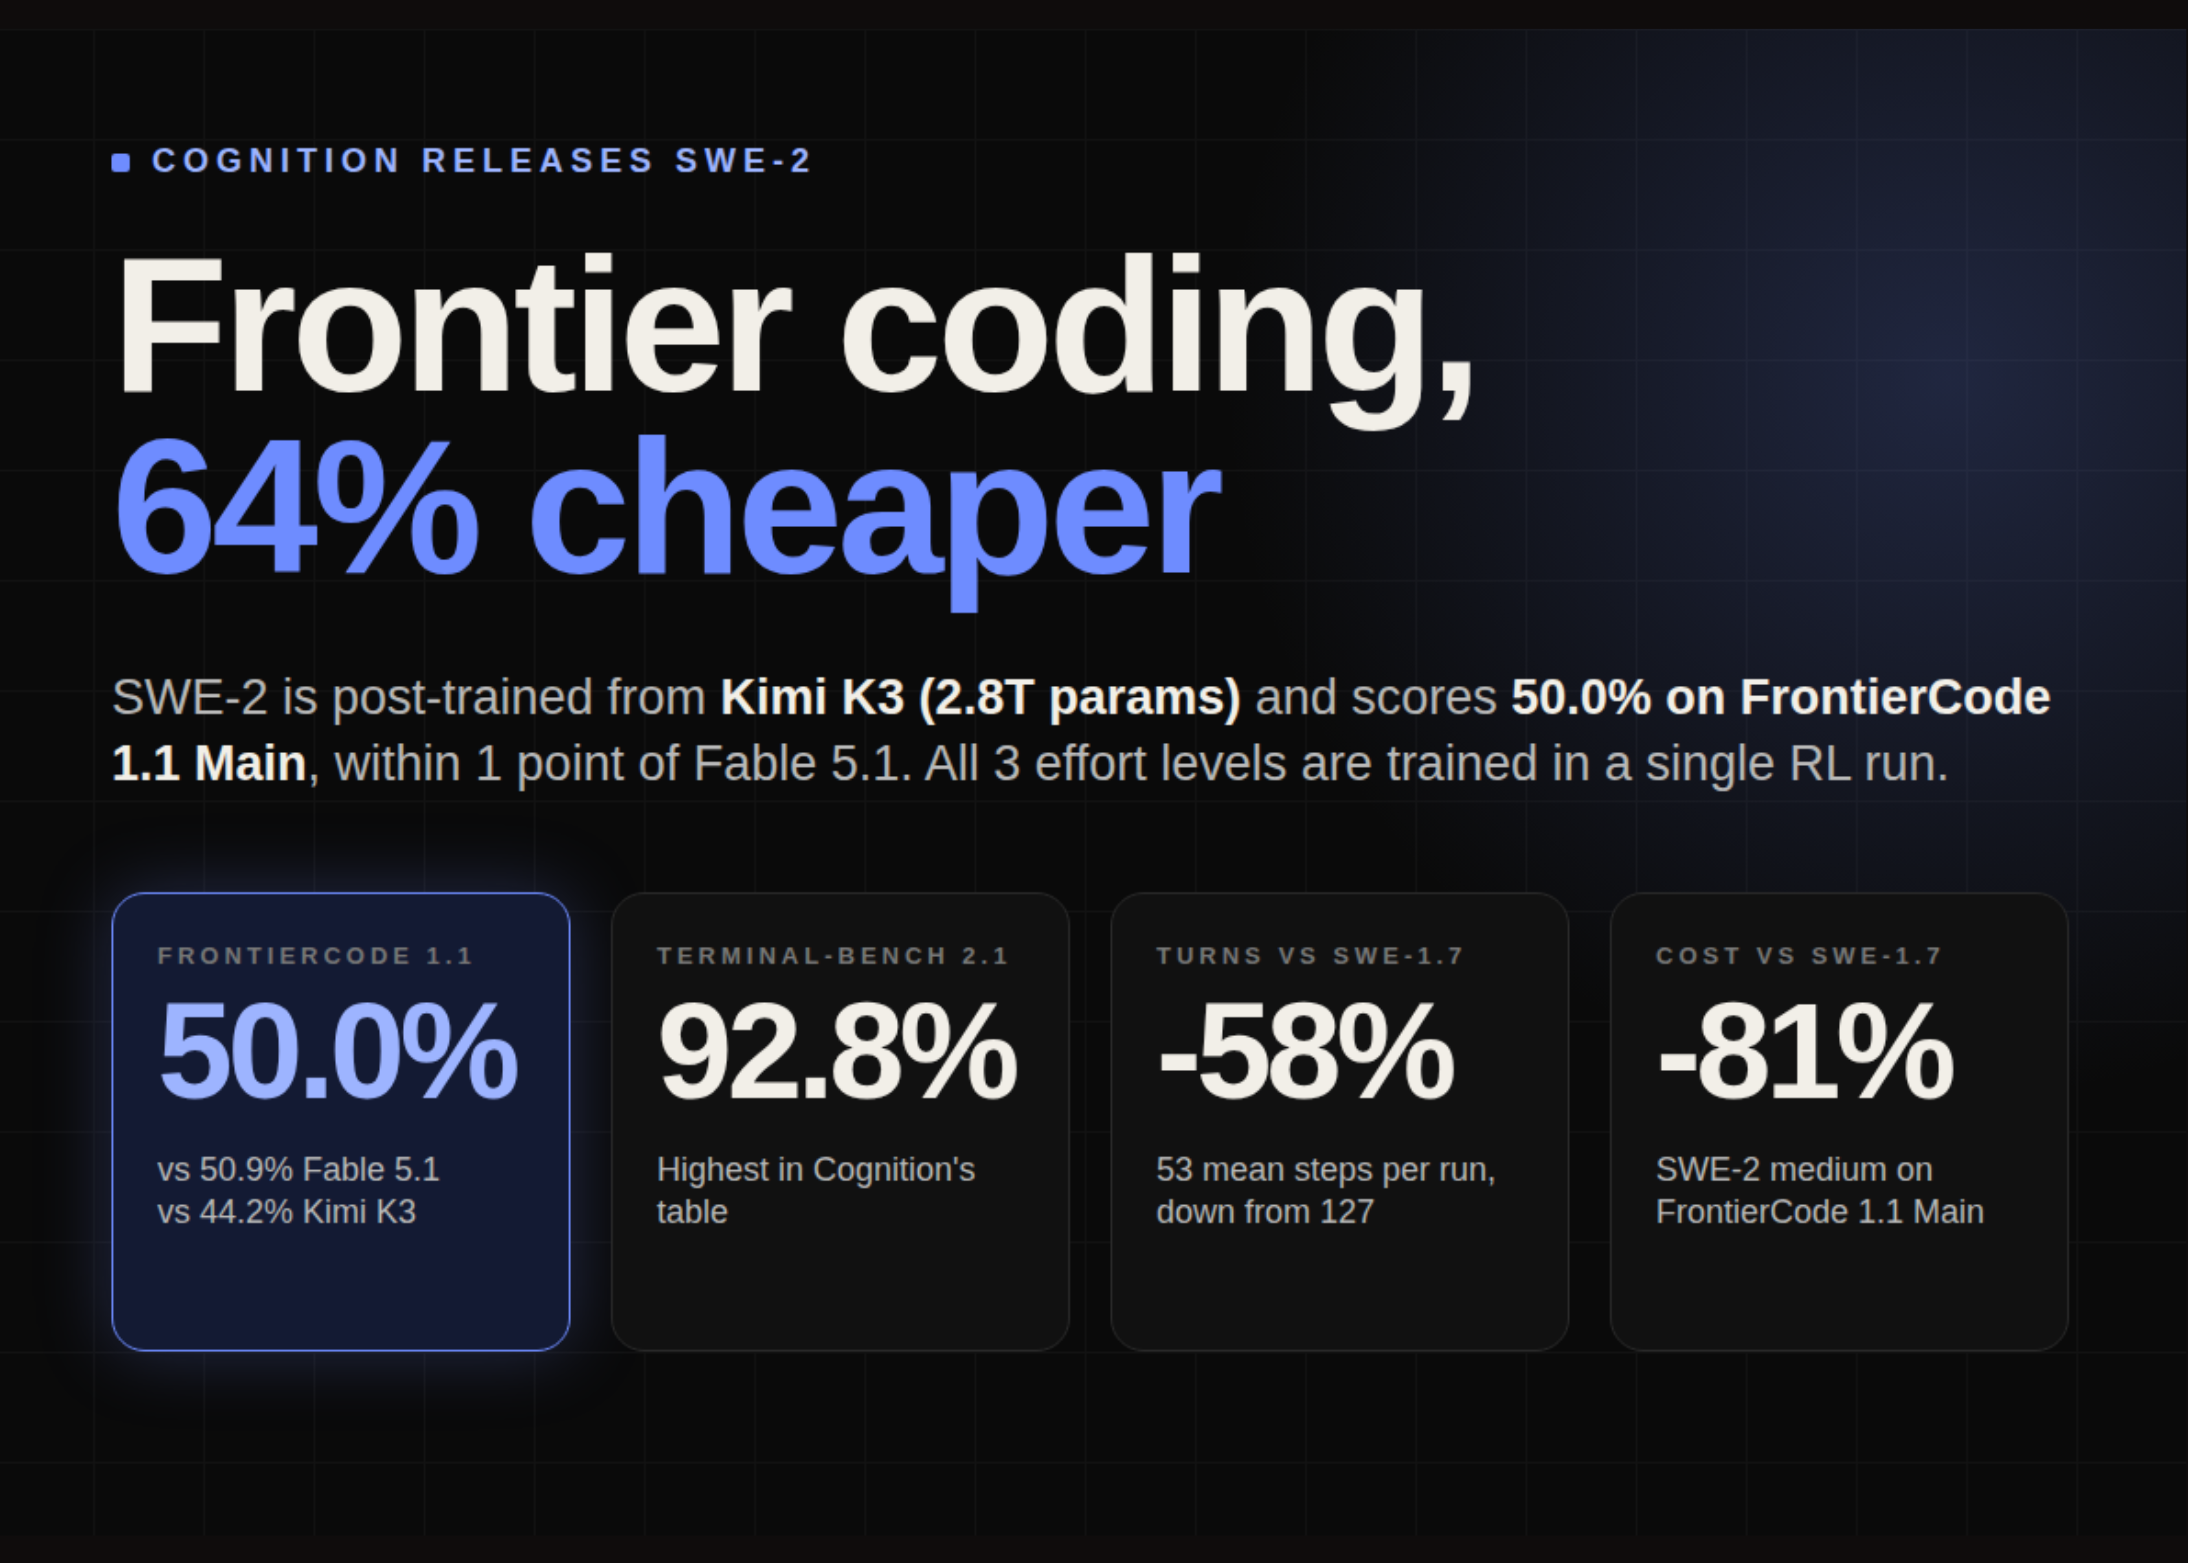
Cognition Releases SWE-2: A Kimi K3 Post-Trained Coding Model That Matches Fable 5.1 on FrontierCode at 64% Lower Cost

Cognition Releases SWE-2: A Kimi K3 Post-Trained Coding Model That Matches Fable 5.1 on FrontierCode at 64% Lower Cost

September 12, 2026
The World’s Smartest AIs Played Poker for ,000

The World’s Smartest AIs Played Poker for $10,000

September 12, 2026
Stocks Under Pressure and Oil Near 0 Kristina Hooper Reveals How to Invest in a Market Pullback

Stocks Under Pressure and Oil Near $100 Kristina Hooper Reveals How to Invest in a Market Pullback

September 8, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!