• bitcoinBitcoin(BTC)$78,361.002.20%
  • ethereumEthereum(ETH)$2,523.991.98%
  • tetherTether(USDT)$1.000.02%
  • binancecoinBNB(BNB)$721.560.78%
  • rippleXRP(XRP)$1.436.31%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$102.853.27%
  • tronTRON(TRX)$0.338390-0.17%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.040.00%
  • zcashZcash(ZEC)$1,167.979.41%
  • HyperliquidHyperliquid(HYPE)$80.223.51%
  • dogecoinDogecoin(DOGE)$0.0838661.72%
  • RainRain(RAIN)$0.014298-5.71%
  • USDSUSDS(USDS)$1.000.01%
  • moneroMonero(XMR)$512.72-1.28%
  • whitebitWhiteBIT Coin(WBT)$81.071.97%
  • chainlinkChainlink(LINK)$11.542.95%
  • leo-tokenLEO Token(LEO)$9.00-0.46%
  • cardanoCardano(ADA)$0.2093382.71%
  • stellarStellar(XLM)$0.1918638.06%
  • Ethena USDeEthena USDe(USDE)$1.000.03%
  • daiDai(DAI)$1.000.01%
  • bitcoin-cashBitcoin Cash(BCH)$223.711.11%
  • USD1USD1(USD1)$1.000.01%
  • litecoinLitecoin(LTC)$53.28-0.78%
  • uniswapUniswap(UNI)$6.556.19%
  • CantonCanton(CC)$0.0971922.20%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.350.43%
  • hedera-hashgraphHedera(HBAR)$0.0776943.54%
  • avalanche-2Avalanche(AVAX)$7.614.09%
  • Global DollarGlobal Dollar(USDG)$1.000.02%
  • nearNEAR Protocol(NEAR)$2.487.45%
  • shiba-inuShiba Inu(SHIB)$0.0000051.92%
  • suiSui(SUI)$0.723.09%
  • crypto-com-chainCronos(CRO)$0.0594613.96%
  • paypal-usdPayPal USD(PYUSD)$1.000.02%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • tether-goldTether Gold(XAUT)$4,290.31-1.02%
  • BittensorBittensor(TAO)$232.940.11%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • MemeCoreMemeCore(M)$1.10-4.07%
  • okbOKB(OKB)$113.511.46%
  • Ripple USDRipple USD(RLUSD)$1.000.02%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.14-0.01%
  • aaveAave(AAVE)$128.482.94%
  • AsterAster(ASTER)$0.702.28%
  • mantleMantle(MNT)$0.572.87%
  • pax-goldPAX Gold(PAXG)$4,294.40-1.03%
  • World Liberty FinancialWorld Liberty Financial(WLFI)$0.0579312.50%
  • OndoOndo(ONDO)$0.3552703.43%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

This AI Paper from China Introduces Video-LaVIT: Unified Video-Language Pre-training with Decoupled Visual-Motional Tokenization

February 22, 2024
in AI & Technology
Reading Time: 4 mins read
A A
This AI Paper from China Introduces Video-LaVIT: Unified Video-Language Pre-training with Decoupled Visual-Motional Tokenization
ShareShareShareShareShare

There has been a recent uptick in the development of general-purpose multimodal AI assistants capable of following visual and written directions, thanks to the remarkable success of Large Language Models (LLMs). By utilizing the impressive reasoning capabilities of LLMs and information found in huge alignment corpus (such as image-text pairs), they demonstrate the immense potential for effectively understanding and creating visual content. Despite their success with image-text data, adaptation for video modality is underexplored in these multimodal LLMs. Video is a more natural fit with human visual perception than still images because of its dynamic nature. To improve AI’s ability to understand the real world, it is very important to learn from video successfully.

By investigating a time-saving video representation that breaks down video into keyframes and temporal motions, a new study by Peking University and Kuaishou Technology overcomes the shortcomings of video-language pretraining. Their work is majorly inspired by the inherent qualities of video data that provide the basis. Most videos are split into multiple shots, and there is usually much redundant information in the video frames within each shot. Including these frames in the generative pretraining of LLMs as tokens is unnecessary. 

Keyframes contain the main visual semantics, and motion vectors show the dynamic evolution of their corresponding keyframe over time; this fact strongly motivates us to divide each movie into these alternating halves. Such deconstructed representation has multiple advantages: 

  1. Utilizing motion vectors with a single keyframe is more efficient for large-scale pretraining than processing consecutive video frames using 3D encoders because it requires fewer tokens to express video temporal dynamics. 
  2. Instead of starting from zero when it comes to modeling time, the model can use the visual knowledge it has gained from a pre-made image-only LLM for its own purposes. 

For these reasons, the team has introduced Video-LaVIT (Language-VIsion Transformer). This novel multimodal pretraining method equips LLMs to understand and produce video material within a cohesive framework. Video-LaVIT has two main components to manage video modalities: a tokenizer and a detokenizer. By employing an established image tokenizer to process the keyframes, the video tokenizer attempts to convert the continuous video data into a sequence of compact discrete tokens similar to a foreign language. Encoding spatiotemporal motions can be encoded by transforming them into a corresponding discrete representation. It greatly improves LLMs’ capacity to understand complex video actions by capturing the time-varying contextual information in retrieved motion vectors. The video detokenizer restores the original continuous pixel space from which the discretized video token produced by LLMs was originally mapped. 

Users may optimize video during training using the same next token prediction objective with different modalities since the video is an alternating discrete visual-motion token sequence. This combined autoregressive pretraining aids in understanding the sequential relationships of various video clips, which is important because video is a time series. 

As a multimodal generalist, VideoLaVIT showed promise in understanding and generating tasks even without additional tuning. Results from extensive quantitative and qualitative tests show that Video-LaVIT outperforms the competition in various tasks, including text-to-video and picture-to-video production, video and image understanding, and more. 


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and Google News. Join our 37k+ ML SubReddit, 41k+ Facebook Community, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our Telegram Channel


YOU MAY ALSO LIKE

The EPA Wants To Stop Regulating Power Plant Emissions

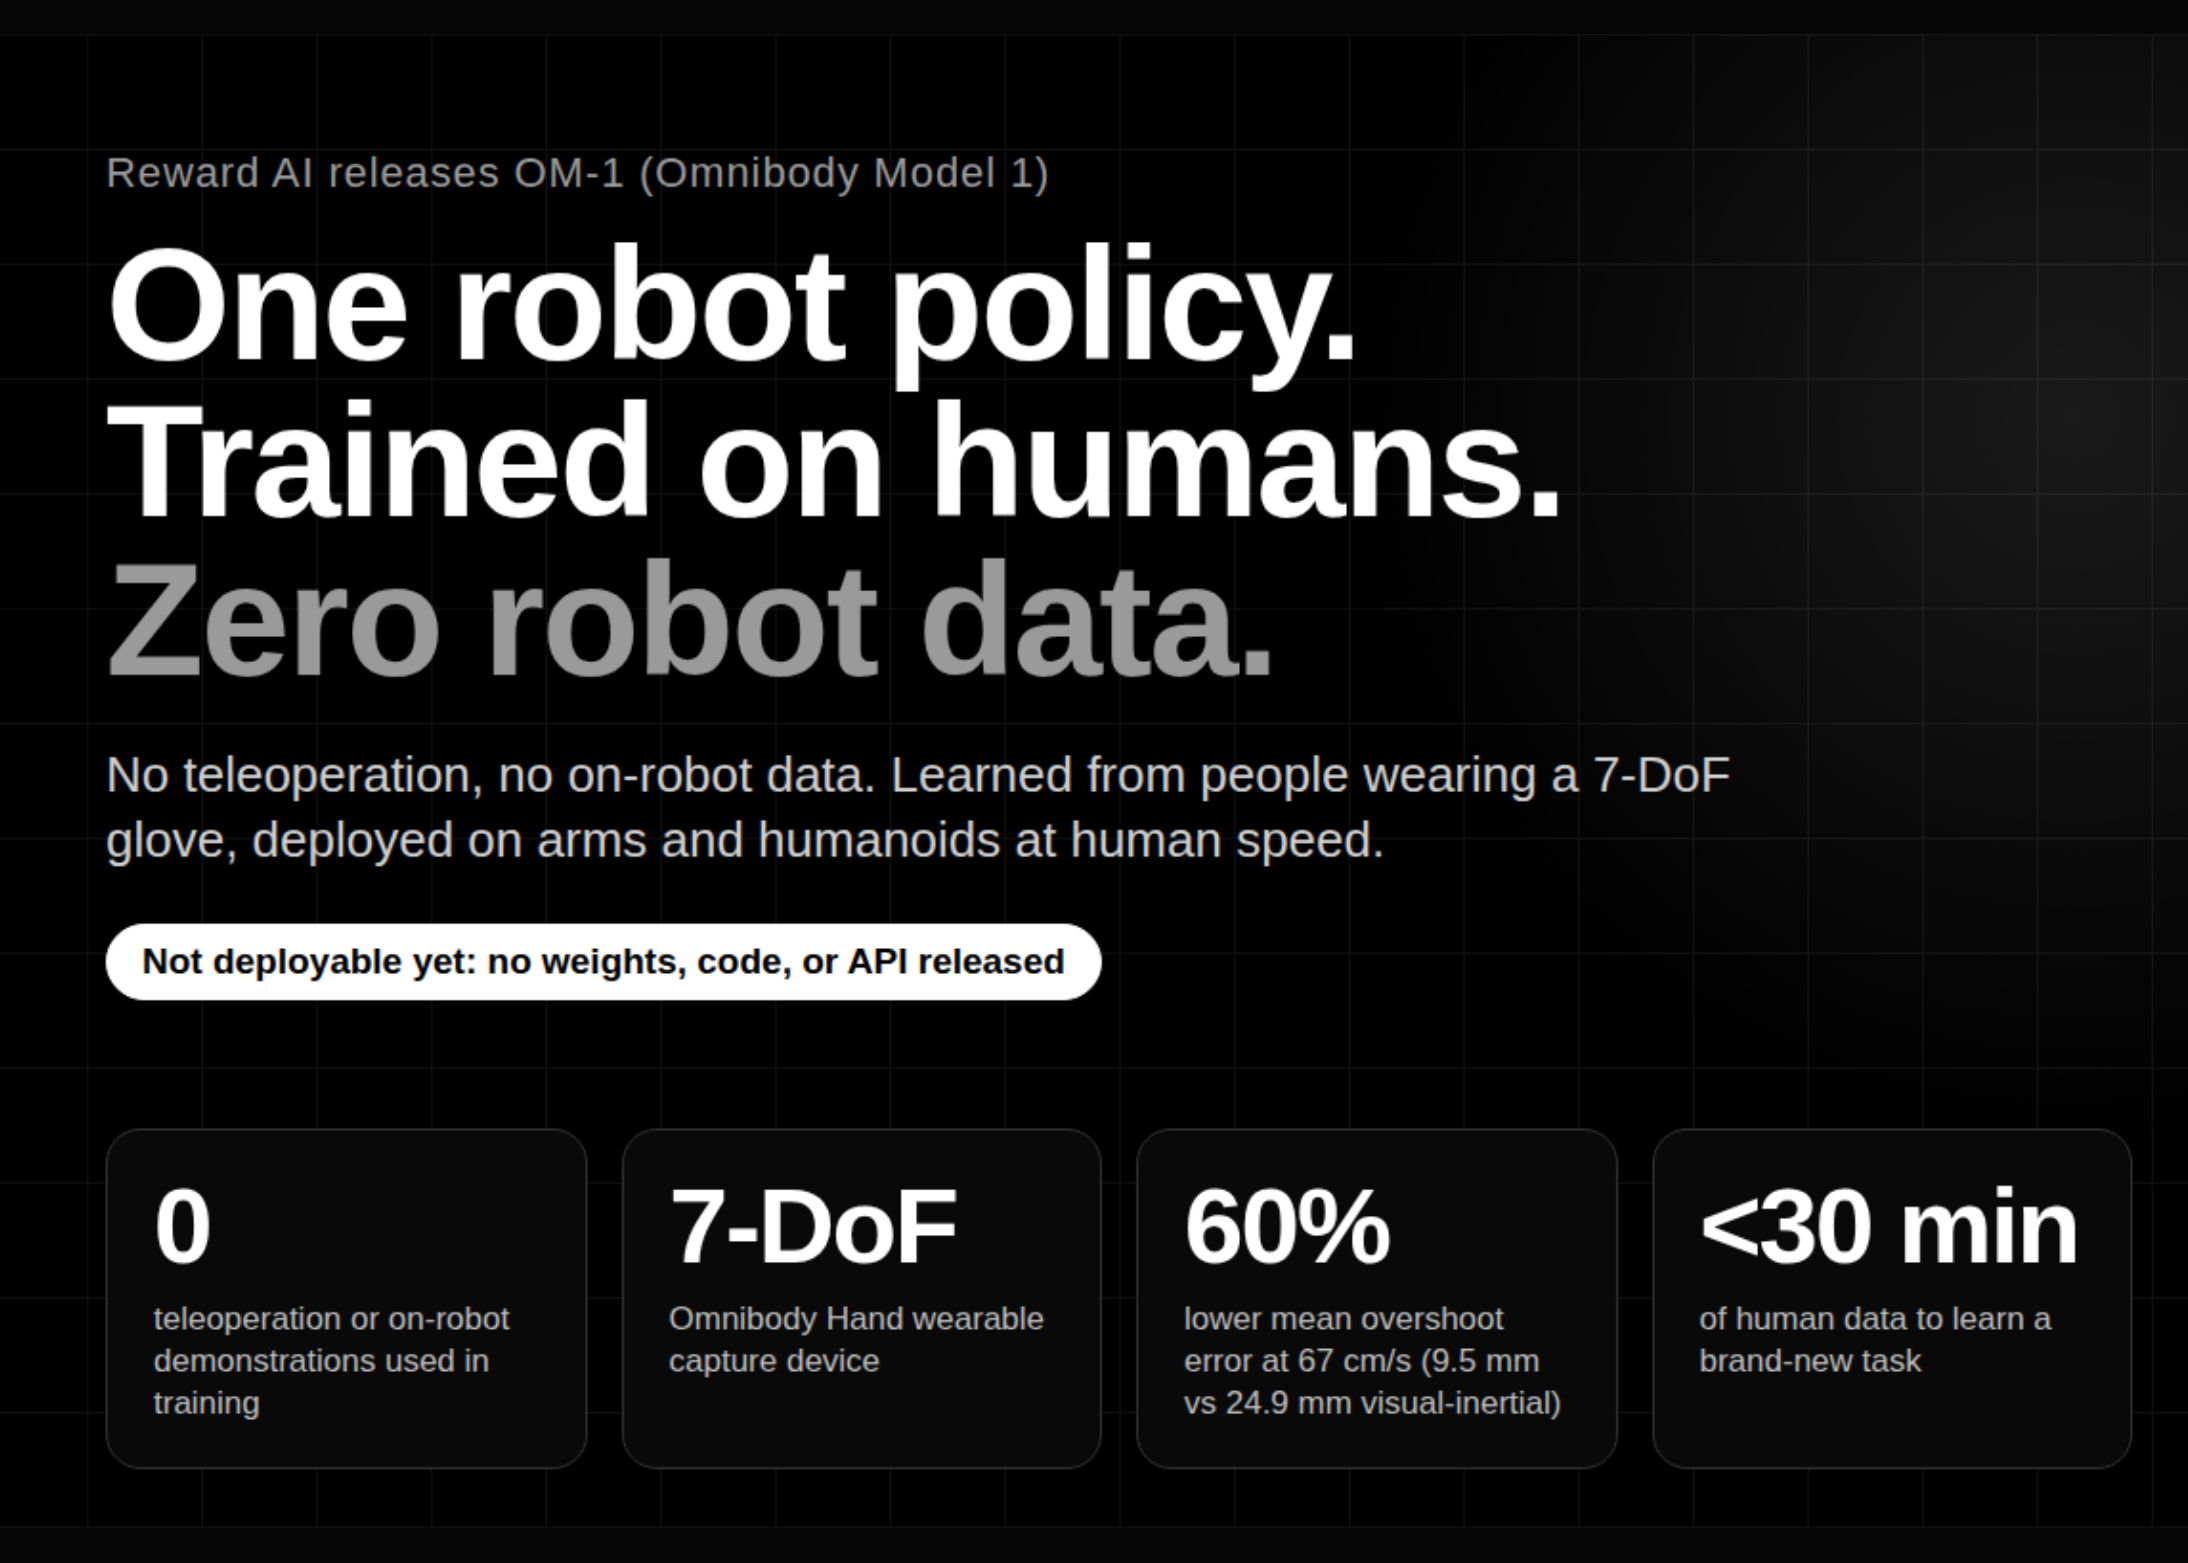
Reward AI Releases OM-1: A Robot Policy Trained on Human Demonstrations Only, With No Teleoperation or On-Robot Data

Dhanshree Shenwai is a Computer Science Engineer and has a good experience in FinTech companies covering Financial, Cards & Payments and Banking domain with keen interest in applications of AI. She is enthusiastic about exploring new technologies and advancements in today’s evolving world making everyone’s life easy.


🚀 LLMWare Launches SLIMs: Small Specialized Function-Calling Models for Multi-Step Automation [Check out all the models]


Credit: Source link

ShareTweetSendSharePin

Related Posts

The EPA Wants To Stop Regulating Power Plant Emissions
AI & Technology

The EPA Wants To Stop Regulating Power Plant Emissions

September 14, 2026
Reward AI Releases OM-1: A Robot Policy Trained on Human Demonstrations Only, With No Teleoperation or On-Robot Data
AI & Technology

Reward AI Releases OM-1: A Robot Policy Trained on Human Demonstrations Only, With No Teleoperation or On-Robot Data

September 14, 2026
How To Force Quit On Your Windows PC
AI & Technology

How To Force Quit On Your Windows PC

September 14, 2026
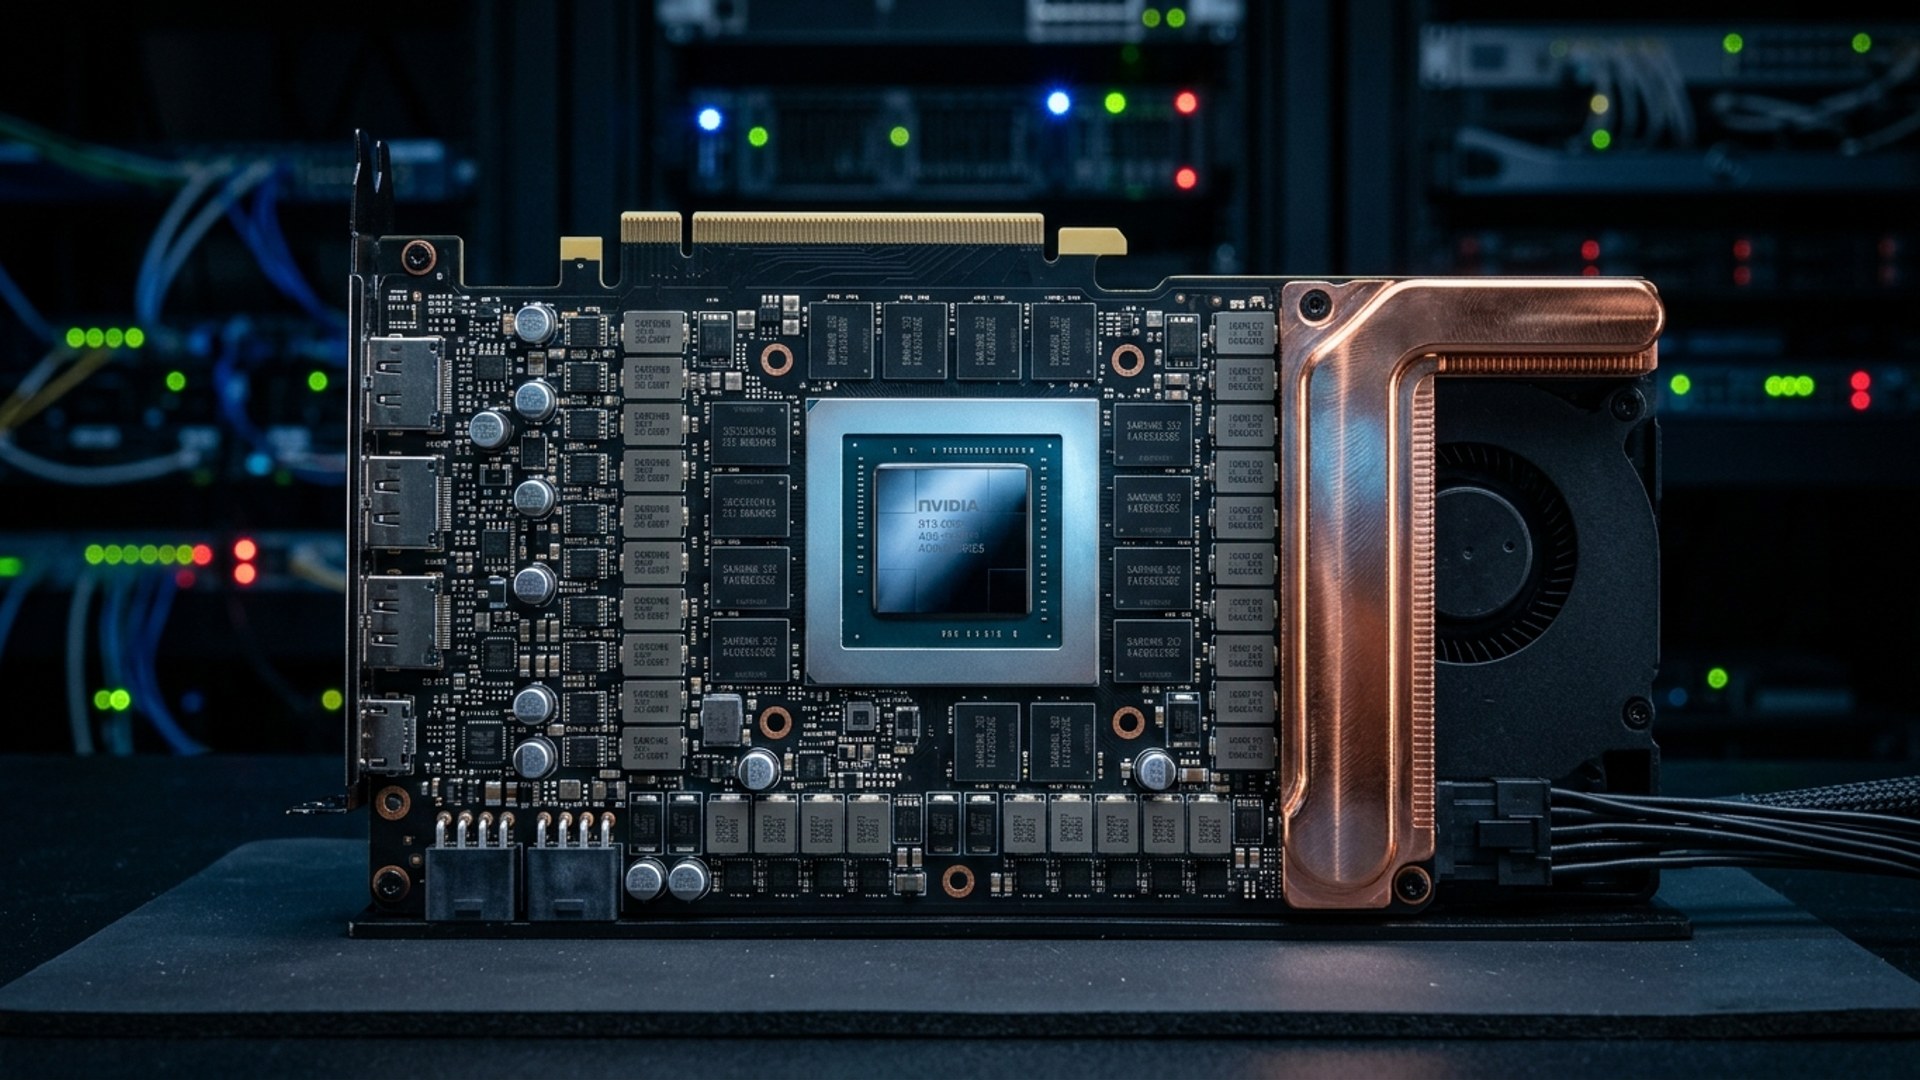
NVIDIA Adds RTX PRO 5500 Blackwell GPU with 84 GB GDDR7 Memory – Unite.AI
AI & Technology

NVIDIA Adds RTX PRO 5500 Blackwell GPU with 84 GB GDDR7 Memory – Unite.AI

September 14, 2026
Next Post
Rural Massachusetts town pushes past fear to hold Pride event

Rural Massachusetts town pushes past fear to hold Pride event

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Student Loan Autopay Now Cuts Your Rate a Full Point

Student Loan Autopay Now Cuts Your Rate a Full Point

September 11, 2026
Apple unveils ,999 foldable ‘iPhone Duo’ as new CEO John Ternus takes reins

Apple unveils $1,999 foldable ‘iPhone Duo’ as new CEO John Ternus takes reins

September 9, 2026
GPT-6 Kalshi AI Trading Bot Week 1 Results – Printing Money?

GPT-6 Kalshi AI Trading Bot Week 1 Results – Printing Money?

September 14, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!