• bitcoinBitcoin(BTC)$79,224.002.44%
  • ethereumEthereum(ETH)$2,538.811.18%
  • tetherTether(USDT)$1.000.02%
  • binancecoinBNB(BNB)$727.180.72%
  • rippleXRP(XRP)$1.488.81%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$103.632.41%
  • tronTRON(TRX)$0.340420-0.31%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.040.00%
  • zcashZcash(ZEC)$1,203.448.41%
  • HyperliquidHyperliquid(HYPE)$81.764.17%
  • dogecoinDogecoin(DOGE)$0.0850330.60%
  • RainRain(RAIN)$0.014333-6.65%
  • USDSUSDS(USDS)$1.000.00%
  • whitebitWhiteBIT Coin(WBT)$81.922.05%
  • moneroMonero(XMR)$513.09-3.59%
  • chainlinkChainlink(LINK)$11.702.28%
  • leo-tokenLEO Token(LEO)$9.00-0.58%
  • cardanoCardano(ADA)$0.2138622.29%
  • stellarStellar(XLM)$0.1954718.69%
  • Ethena USDeEthena USDe(USDE)$1.000.02%
  • daiDai(DAI)$1.00-0.01%
  • bitcoin-cashBitcoin Cash(BCH)$227.201.28%
  • USD1USD1(USD1)$1.000.02%
  • litecoinLitecoin(LTC)$54.13-1.49%
  • uniswapUniswap(UNI)$6.614.47%
  • CantonCanton(CC)$0.0977791.91%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.36-0.05%
  • hedera-hashgraphHedera(HBAR)$0.0783492.28%
  • avalanche-2Avalanche(AVAX)$7.612.39%
  • nearNEAR Protocol(NEAR)$2.578.89%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • shiba-inuShiba Inu(SHIB)$0.0000051.93%
  • suiSui(SUI)$0.742.72%
  • crypto-com-chainCronos(CRO)$0.0592311.16%
  • paypal-usdPayPal USD(PYUSD)$1.000.02%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • BittensorBittensor(TAO)$238.800.91%
  • tether-goldTether Gold(XAUT)$4,307.20-0.96%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • MemeCoreMemeCore(M)$1.08-6.04%
  • okbOKB(OKB)$114.490.82%
  • Ripple USDRipple USD(RLUSD)$1.000.02%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.14-0.05%
  • aaveAave(AAVE)$129.421.97%
  • AsterAster(ASTER)$0.700.65%
  • mantleMantle(MNT)$0.571.33%
  • pax-goldPAX Gold(PAXG)$4,311.37-0.96%
  • World Liberty FinancialWorld Liberty Financial(WLFI)$0.0582192.19%
  • BitwayBitway(BTW)$0.68-2.85%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Enhancing Language Model Alignment through Reward Transformation and Multi-Objective Optimization

February 13, 2024
in AI & Technology
Reading Time: 5 mins read
A A
Enhancing Language Model Alignment through Reward Transformation and Multi-Objective Optimization
ShareShareShareShareShare

The current study examines how well LLMs align with desirable attributes, such as helpfulness, harmlessness, factual accuracy, and creativity. The primary focus is on a two-stage process that involves learning a reward model from human preferences and then aligning the language model to maximize this reward. It addresses two key issues: 

  1. Improving alignment by considering different transformations of the learned reward. 
  2. Effectively combining multiple reward models when aligning language models to various attributes. 

However, the challenge lies in the need for a precisely defined goal for alignment, which leads to exploring various transformation and aggregation methods without a clear guiding principle.

Researchers from the University of Chicago, Google Research, Google DeepMind, and Stanford University mention the problem of aligning language models to human preferences by learning a reward model from preference data and updating the language model, proposing a transformation technique for rewards and the combination of multiple reward models. The derived transformation emphasizes improving poorly performing outputs and enables principled aggregation of rewards, leading to substantial improvements in aligning language models to be helpful and harmless.

Various techniques address reward hacking in Reinforcement Learning from Human Feedback (RLHF), including reward model averaging, constrained optimization, and iterative human preference collection. By proposing a complementary method, the study explores aligning language models to multiple objectives, with common approaches involving weighted sum combinations of individual reward models. The transformation technique presented applies to alignment strategies maximizing expected utility. While some alignment methods use preference labels directly, rankings are computed from an aggregate when aligning to multiple properties. It addresses the need for a bounded utility function.

The research mentions a transformation technique for aligning language models to human preferences by learning a reward model from preference data and updating the language model. The researchers use a probabilistic interpretation of the alignment procedure to identify a natural choice for transformation for rewards learned from Bradley-Terry preference models. The derived transformation emphasizes improving poorly performing outputs and mitigates underfitting and reward hacking. The study also explores the combination of multiple reward models and enables principled aggregation of rewards by linking summation to logical conjunction. Experiments are conducted, aligning language models to be helpful and harmless using RLHF  and showing substantial improvements over the baseline approach.
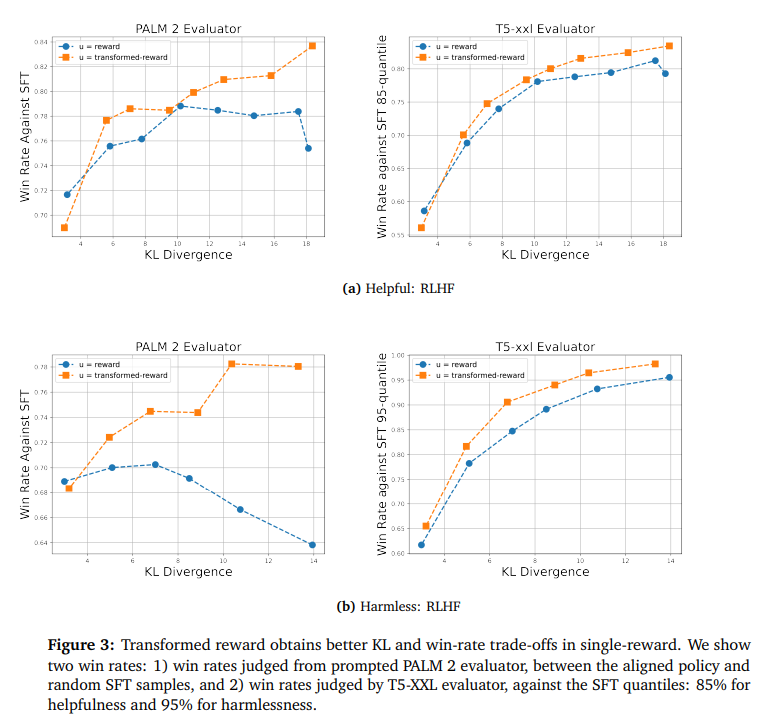
Compared to the baseline approach, the approach demonstrates substantial improvements in aligning language models to be helpful and harmless using RLHF. The transformation technique for rewards and combining multiple reward models show promising results in aligning language models to human preferences. Summing the transformed rewards corresponds better to logical AND, leading to more balanced reward distributions and outperforming the baseline reward method. The transformed-aligned model outperforms the baseline in best-of-k and low-KL cases, while in high-KL cases, the transformed-reward dramatically outperforms the raw-reward baseline. The experiments conducted in the study provide evidence of the effectiveness of the mentioned methods in improving the alignment of language models to human preferences.

In conclusion, The research proposes a technique for aligning language models to human preferences, focusing on improving poorly performing outputs and enabling principled aggregation of rewards. The transformation for rewards learned from Bradley-Terry preference models has two essential properties: it improves poorly performing outputs and allows for principled reward aggregation. Experiments conducted using RLHF demonstrate substantial improvements over the baseline approach, proving the effectiveness of the proposed methods. It emphasizes the importance of considering both helpfulness and harmlessness in aligning language models, and the developed methods provide a promising approach to achieving this alignment by combining multiple reward models and using logical conjunction in reward aggregation.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and Google News. Join our 36k+ ML SubReddit, 41k+ Facebook Community, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our Telegram Channel

YOU MAY ALSO LIKE

NVIDIA Adds RTX PRO 5500 Blackwell GPU with 84 GB GDDR7 Memory – Unite.AI

You Can Use Gemini To Help You Organize Your Files On Google Drive

Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.


🚀 LLMWare Launches SLIMs: Small Specialized Function-Calling Models for Multi-Step Automation [Check out all the models]


Credit: Source link

ShareTweetSendSharePin

Related Posts

NVIDIA Adds RTX PRO 5500 Blackwell GPU with 84 GB GDDR7 Memory – Unite.AI
AI & Technology

NVIDIA Adds RTX PRO 5500 Blackwell GPU with 84 GB GDDR7 Memory – Unite.AI

September 14, 2026
You Can Use Gemini To Help You Organize Your Files On Google Drive
AI & Technology

You Can Use Gemini To Help You Organize Your Files On Google Drive

September 14, 2026
Anthropic Launches Claude for Financial Advisors With Partner Connectors – Unite.AI
AI & Technology

Anthropic Launches Claude for Financial Advisors With Partner Connectors – Unite.AI

September 14, 2026
How To Fix Outlook’s “Your Message Can’t Be Displayed Right Now” Error
AI & Technology

How To Fix Outlook’s “Your Message Can’t Be Displayed Right Now” Error

September 14, 2026
Next Post
Federal judge restricts White House from contact with social media companies

Federal judge restricts White House from contact with social media companies

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
DGRO: The 1.89% Yield Is The Least Of Its Problems (NYSEARCA:DGRO)

DGRO: The 1.89% Yield Is The Least Of Its Problems (NYSEARCA:DGRO)

September 12, 2026
Mamdani highlights the resilience and unity of New York City on 9/11 anniversary

Mamdani highlights the resilience and unity of New York City on 9/11 anniversary

September 13, 2026
NASA And IBM Made An AI Model For Exploring The Moon

NASA And IBM Made An AI Model For Exploring The Moon

September 10, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!