• bitcoinBitcoin(BTC)$77,111.00-3.54%
  • ethereumEthereum(ETH)$2,222.75-4.04%
  • tetherTether(USDT)$1.000.01%
  • binancecoinBNB(BNB)$698.52-6.00%
  • rippleXRP(XRP)$1.24-3.73%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$95.57-4.65%
  • tronTRON(TRX)$0.3344430.87%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-0.38%
  • HyperliquidHyperliquid(HYPE)$91.430.97%
  • zcashZcash(ZEC)$1,237.18-2.73%
  • dogecoinDogecoin(DOGE)$0.075531-4.26%
  • moneroMonero(XMR)$587.41-1.76%
  • USDSUSDS(USDS)$1.000.08%
  • whitebitWhiteBIT Coin(WBT)$73.91-3.71%
  • leo-tokenLEO Token(LEO)$9.42-0.51%
  • chainlinkChainlink(LINK)$11.05-4.64%
  • cardanoCardano(ADA)$0.192229-4.36%
  • stellarStellar(XLM)$0.166867-2.31%
  • bitcoin-cashBitcoin Cash(BCH)$285.652.61%
  • nearNEAR Protocol(NEAR)$4.25-4.12%
  • RainRain(RAIN)$0.006620-0.21%
  • daiDai(DAI)$1.000.05%
  • Ethena USDeEthena USDe(USDE)$1.00-0.06%
  • litecoinLitecoin(LTC)$55.36-4.19%
  • uniswapUniswap(UNI)$6.88-4.01%
  • USD1USD1(USD1)$1.00-0.10%
  • CantonCanton(CC)$0.096343-6.06%
  • avalanche-2Avalanche(AVAX)$8.25-6.01%
  • suiSui(SUI)$0.89-4.26%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.16-4.23%
  • hedera-hashgraphHedera(HBAR)$0.071886-3.15%
  • tether-goldTether Gold(XAUT)$3,922.25-2.53%
  • Global DollarGlobal Dollar(USDG)$1.000.04%
  • paypal-usdPayPal USD(PYUSD)$1.000.06%
  • shiba-inuShiba Inu(SHIB)$0.000005-2.75%
  • quant-networkQuant(QNT)$193.26-0.31%
  • BittensorBittensor(TAO)$231.75-7.63%
  • crypto-com-chainCronos(CRO)$0.051501-4.19%
  • Ripple USDRipple USD(RLUSD)$1.000.02%
  • EthenaEthena(ENA)$0.186745-8.63%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.04%
  • Circle USYCCircle USYC(USYC)$1.140.03%
  • okbOKB(OKB)$110.80-1.38%
  • MemeCoreMemeCore(M)$0.97-9.06%
  • pepePepe(PEPE)$0.0000056.31%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • aaveAave(AAVE)$125.02-5.50%
  • OndoOndo(ONDO)$0.390603-5.58%
  • BitwayBitway(BTW)$1.25-29.82%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Google DeepMind Researchers Propose WARM: A Novel Approach to Tackle Reward Hacking in Large Language Models Using Weight-Averaged Reward Models

January 26, 2024
in AI & Technology
Reading Time: 4 mins read
A A
Google DeepMind Researchers Propose WARM: A Novel Approach to Tackle Reward Hacking in Large Language Models Using Weight-Averaged Reward Models
ShareShareShareShareShare

In recent times, Large Language Models (LLMs) have gained popularity for their ability to respond to user queries in a more human-like manner, accomplished through reinforcement learning. However, aligning these LLMs with human preferences in reinforcement learning from human feedback (RLHF) can lead to a phenomenon known as reward hacking. This occurs when LLMs exploit flaws in the reward model (RM), achieving high rewards without fulfilling the underlying objectives, as illustrated in Figure 1(b). Reward hacking raises concerns such as degraded performance, checkpoint selection challenges, potential biases, and, most critically, safety risks.

The primary challenges identified in designing RMs to mitigate reward hacking include distribution shifts and inconsistent preferences in the preference dataset. Distribution shifts arise due to policy drift during RL, leading to a deviation from the offline preference dataset. Inconsistent preferences stem from noisy binary labels, introducing low inter-labeler agreement and impacting RM robustness. To address these challenges, existing approaches have explored strategies like KL regularization, active learning, and prediction ensembling (ENS). However, these methods face efficiency issues, reliability concerns, and struggle with preference inconsistencies.

To tackle these challenges, this paper proposes Weight Averaged Reward Models (WARM) (illustrated in Figure 1(a)), a simple, efficient, and scalable strategy for obtaining a reliable and robust RM. WARM combines multiple RMs through linear interpolation in the weight space, providing benefits such as efficiency, improved reliability under distribution shifts, and enhanced robustness to label corruption. The diversity across fine-tuned weights is a key contributor to the effectiveness of WARM.

WARM is compared to prediction ensembling (ENS), showcasing its efficiency and practicality by requiring a single model at inference time, eliminating memory and inference overheads. Empirical results indicate that WARM performs similarly to ENS in terms of variance reduction but exhibits superiority under distribution shifts. The paper introduces the concept of linear mode connectivity (LMC) as a key factor in WARM’s success, demonstrating its ability to memorize less and generalize better than ensembling predictions. There are 3 observations that are made in the experiments and are empirically proven in Figure 3 and 4:

  • Observation 1 (LMC): The accuracy of the interpolated model is at least as good as the interpolation of the individual accuracies.
  • Observation 2 (WA and ENS): Weight averaging and prediction ensembling perform similarly.
  • Observation 3 (WA and ENS): The accuracy gains of WA over ENS grow as data moves away from the training distribution. 

The benefits of WARM extend beyond its primary goals. It aligns with the updatable machine learning paradigm, allowing parallelization in federated learning scenarios. WARM could contribute to privacy and bias mitigation by reducing memorization of private preferences. The method shows potential for combining RMs trained on different datasets, supporting iterative and evolving preferences. Further exploration includes extending WARM to direct preference optimization strategies.

Despite its innovation, WARM has limitations compared to prediction ensembling methods, including potential limitations in handling diverse architectures and uncertainty estimation. WARM does not entirely eliminate spurious correlations or biases in preference data, suggesting the need for additional methods for a comprehensive solution. Lastly, WARM focuses on enhancing reward modeling and should be considered within the broader context of responsible AI to address safety risks from misalignment.

In conclusion, Weight Averaged Reward Models (WARM) offer a promising solution to challenges in reward modeling, enhancing alignment in RLHF. The paper’s empirical results and theoretical insights position WARM as a valuable contribution toward creating more aligned, transparent, and effective AI systems.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our 36k+ ML SubReddit, 41k+ Facebook Community, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our Telegram Channel


YOU MAY ALSO LIKE

CXMT Q3 Revenue Rises 613% as DRAM Shortage Swings It to Profit – Unite.AI

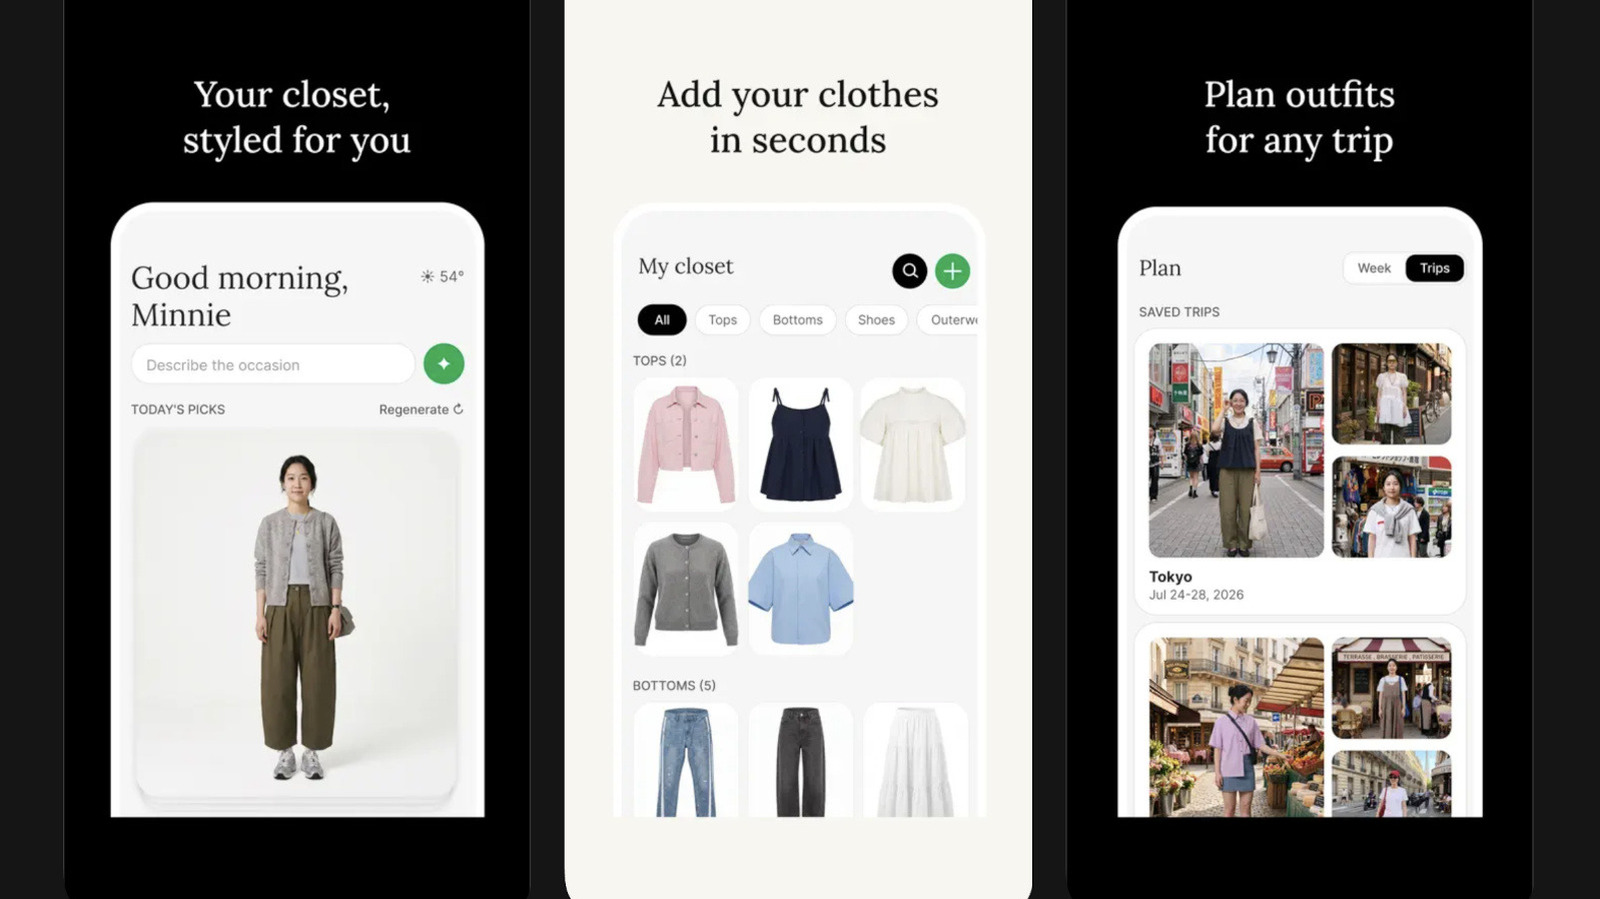
Meta Quietly Launches An AI Fashion App For Virtually Trying On Clothes

Vineet Kumar is a consulting intern at MarktechPost. He is currently pursuing his BS from the Indian Institute of Technology(IIT), Kanpur. He is a Machine Learning enthusiast. He is passionate about research and the latest advancements in Deep Learning, Computer Vision, and related fields.


🧑‍💻 [FREE AI WEBINAR]’LangChain for Multimodal Apps: Chat With Text/Image Data’ (Jan 26, 2024)


Credit: Source link

ShareTweetSendSharePin

Related Posts

CXMT Q3 Revenue Rises 613% as DRAM Shortage Swings It to Profit – Unite.AI
AI & Technology

CXMT Q3 Revenue Rises 613% as DRAM Shortage Swings It to Profit – Unite.AI

October 30, 2026
Meta Quietly Launches An AI Fashion App For Virtually Trying On Clothes
AI & Technology

Meta Quietly Launches An AI Fashion App For Virtually Trying On Clothes

October 30, 2026
Waymo And Toyota Will Soon Start Testing Their Robotaxis In Japan
AI & Technology

Waymo And Toyota Will Soon Start Testing Their Robotaxis In Japan

October 30, 2026
Cognizant Forms OpenAI Frontier Capability Group of 25,000+ Professionals – Unite.AI
AI & Technology

Cognizant Forms OpenAI Frontier Capability Group of 25,000+ Professionals – Unite.AI

October 30, 2026
Next Post
First Citizens BancShares, Inc. (FCNCA) Q4 2023 Earnings Call Transcript

First Citizens BancShares, Inc. (FCNCA) Q4 2023 Earnings Call Transcript

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Bretton Fund Q3 2026 Shareholder Letter

Bretton Fund Q3 2026 Shareholder Letter

October 25, 2026
Helicopter puts on a show at California country club

Helicopter puts on a show at California country club

October 28, 2026
12-foot alligator caught after deadly attack in Florida

12-foot alligator caught after deadly attack in Florida

October 23, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!