• bitcoinBitcoin(BTC)$77,301.000.19%
  • ethereumEthereum(ETH)$2,242.781.52%
  • tetherTether(USDT)$1.000.12%
  • binancecoinBNB(BNB)$703.77-1.28%
  • rippleXRP(XRP)$1.252.80%
  • usd-coinUSDC(USDC)$1.000.12%
  • solanaSolana(SOL)$96.671.78%
  • tronTRON(TRX)$0.325399-8.83%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-0.31%
  • zcashZcash(ZEC)$1,275.141.24%
  • HyperliquidHyperliquid(HYPE)$89.63-1.16%
  • dogecoinDogecoin(DOGE)$0.0758091.29%
  • moneroMonero(XMR)$592.16-3.63%
  • USDSUSDS(USDS)$1.000.45%
  • chainlinkChainlink(LINK)$11.608.37%
  • whitebitWhiteBIT Coin(WBT)$74.220.56%
  • leo-tokenLEO Token(LEO)$9.461.19%
  • cardanoCardano(ADA)$0.1941562.72%
  • stellarStellar(XLM)$0.1694214.25%
  • bitcoin-cashBitcoin Cash(BCH)$290.604.82%
  • nearNEAR Protocol(NEAR)$4.366.97%
  • daiDai(DAI)$1.000.07%
  • Ethena USDeEthena USDe(USDE)$1.000.17%
  • RainRain(RAIN)$0.006278-3.80%
  • uniswapUniswap(UNI)$7.045.92%
  • litecoinLitecoin(LTC)$55.330.51%
  • CantonCanton(CC)$0.0980646.15%
  • USD1USD1(USD1)$1.000.13%
  • avalanche-2Avalanche(AVAX)$8.623.70%
  • suiSui(SUI)$0.904.31%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.191.81%
  • hedera-hashgraphHedera(HBAR)$0.0721893.80%
  • tether-goldTether Gold(XAUT)$3,878.59-2.85%
  • Global DollarGlobal Dollar(USDG)$1.000.08%
  • quant-networkQuant(QNT)$195.398.54%
  • paypal-usdPayPal USD(PYUSD)$1.000.36%
  • shiba-inuShiba Inu(SHIB)$0.0000054.39%
  • BittensorBittensor(TAO)$237.172.25%
  • crypto-com-chainCronos(CRO)$0.0517792.19%
  • EthenaEthena(ENA)$0.1919095.37%
  • Ripple USDRipple USD(RLUSD)$1.000.14%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.30%
  • Circle USYCCircle USYC(USYC)$1.140.03%
  • okbOKB(OKB)$110.770.92%
  • MemeCoreMemeCore(M)$0.95-4.74%
  • pepePepe(PEPE)$0.0000054.34%
  • OndoOndo(ONDO)$0.41621710.08%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • aaveAave(AAVE)$130.957.98%
  • Pump.funPump.fun(PUMP)$0.0041355.16%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Google AI Presents PaLI-3: A Smaller, Faster, and Stronger Vision Language Model (VLM) that Compares Favorably to Similar Models that are 10x Larger

October 22, 2023
in AI & Technology
Reading Time: 4 mins read
A A
Google AI Presents PaLI-3: A Smaller, Faster, and Stronger Vision Language Model (VLM) that Compares Favorably to Similar Models that are 10x Larger
ShareShareShareShareShare

Vision Language Model (VLM) is an advanced artificial intelligence system that combines natural language understanding with image recognition capabilities. Like OpenAI’s CLIP and Google’s BigGAN, VLMs can comprehend textual descriptions and interpret images, enabling various applications in fields such as computer vision, content generation, and human-computer interaction. They have demonstrated impressive capabilities in understanding and generating text in context with visual content, making them a pivotal technology in the AI landscape.

Researchers from Google Research, Google DeepMind, and Google Cloud contrasts Vision Transformer (ViT) models pre-trained with classification versus contrastive objectives, with contrastive pretrained models, particularly SigLIP-based PaLI, outperforming in multimodal tasks, notably localization and text understanding. The researchers scaled the SigLIP image encoder to 2 billion parameters, achieving a new multilingual cross-modal retrieval state-of-the-art. Their study advocates pre-training visual encoders on web-scale image-text data instead of classification-style data. Their approach reveals the benefits of scaling up classification pretrained image encoders, as demonstrated by PaLI-X in large Vision Language Models.

Their study delves into scaling VLM while underscoring the importance of smaller-scale models for practicality and efficient research. It introduces PaLI-3, a 5-billion-parameter VLM with competitive results. PaLI-3’s training process involves contrastive pre-training of the image encoder on web-scale data, improved dataset mixing, and higher-resolution training. A 2-billion-parameter multilingual contrastive vision model is introduced. Ablation studies confirm the superiority of contrastively pretrained models, especially in tasks related to localization and visually-situated text understanding.

Their approach employs a pre-trained ViT model as the image encoder, specifically ViT-G14, using the SigLIP training recipe. ViT-G14 has around 2 billion parameters and serves as the vision backbone for PaLI-3. Contrastive pre-training involves embedding images and texts separately and classifying their correspondence. Visual tokens from ViT’s output are projected and combined with text tokens. These inputs are then processed by a 3 billion parameter UL2 encoder-decoder language model for text generation, typically driven by task-specific prompts like VQA questions.

PaLI-3 excels compared to larger counterparts, particularly in localization and visually situated text understanding. The SigLIP-based PaLI model, with contrastive image encoder pre-training, establishes a new multilingual cross-modal retrieval state-of-the-art. The full PaLI-3 model outperforms the state-of-the-art in referring expression segmentation and maintains low error rates across subgroups in detection tasks. Contrastive pre-training proves more effective for localization tasks. The ViT-G image encoder of PaLI-3 excels in multiple classification and cross-modal retrieval tasks.

In conclusion, their research emphasizes the benefits of contrastive pre-training, exemplified by the SigLIP approach, for enhanced and efficient VLMs. The smaller 5-billion-parameter SigLIP-based PaLI-3 model excels in localization and text understanding, outperforming larger counterparts on diverse multimodal benchmarks. Contrastive pre-training of the image encoder in PaLI-3 also achieves a new multilingual cross-modal retrieval state-of-the-art. Their study underscores the need for comprehensive investigations into various aspects of VLM training beyond image encoder pre-training to enhance model performance further.


Check out the Paper. All Credit For This Research Goes To the Researchers on This Project. Also, don’t forget to join our 31k+ ML SubReddit, 40k+ Facebook Community, Discord Channel, and Email Newsletter, where we share the latest AI research news, cool AI projects, and more.

If you like our work, you will love our newsletter..

We are also on WhatsApp. Join our AI Channel on Whatsapp..


YOU MAY ALSO LIKE

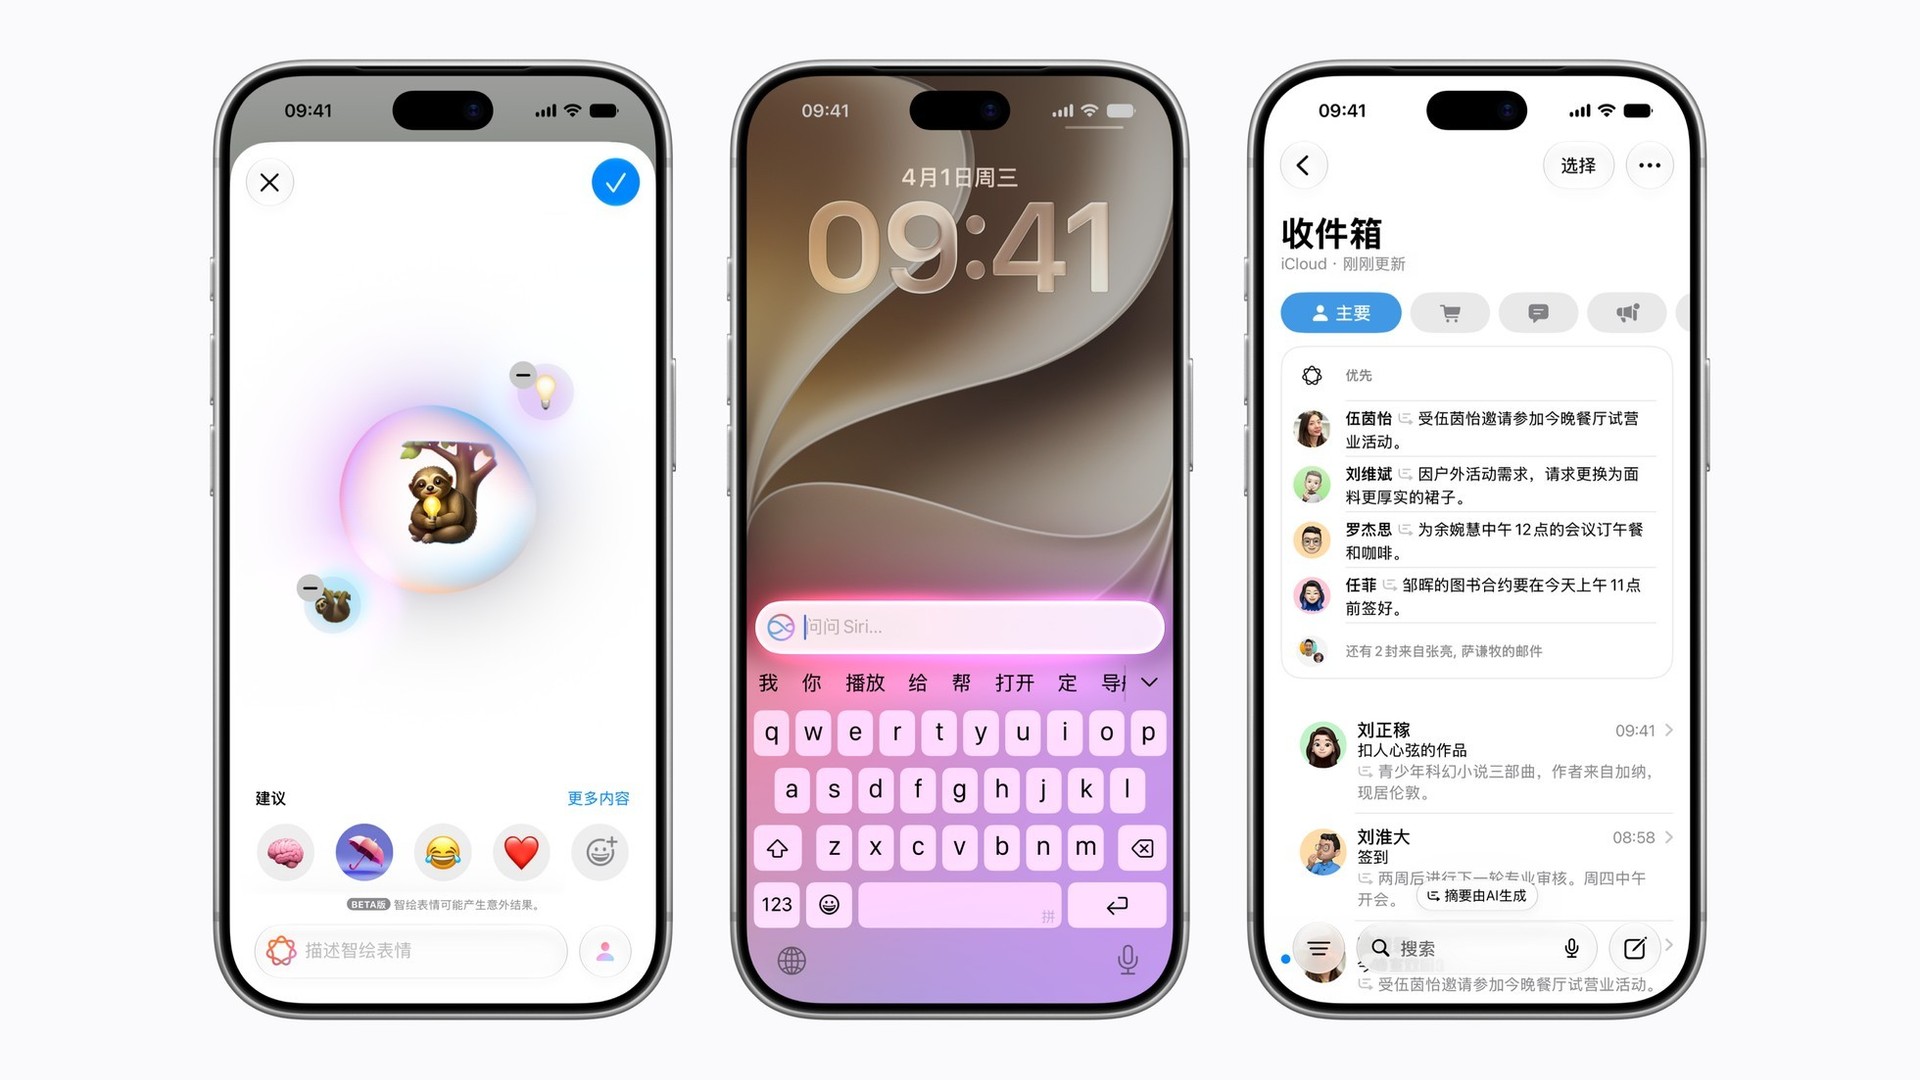
Apple Brings First Apple Intelligence Features to China in iOS 27.3 – Unite.AI

Powerlattice Raises $86M in Equity Offering, SEC Filing Shows – Unite.AI

Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.


▶️ Now Watch AI Research Updates On Our Youtube Channel [Watch Now]

Credit: Source link

ShareTweetSendSharePin

Related Posts

Apple Brings First Apple Intelligence Features to China in iOS 27.3 – Unite.AI
AI & Technology

Apple Brings First Apple Intelligence Features to China in iOS 27.3 – Unite.AI

October 30, 2026
Powerlattice Raises M in Equity Offering, SEC Filing Shows – Unite.AI
AI & Technology

Powerlattice Raises $86M in Equity Offering, SEC Filing Shows – Unite.AI

October 30, 2026
Meta Settles Another Social Media Addiction Case Just Before Trial
AI & Technology

Meta Settles Another Social Media Addiction Case Just Before Trial

October 30, 2026
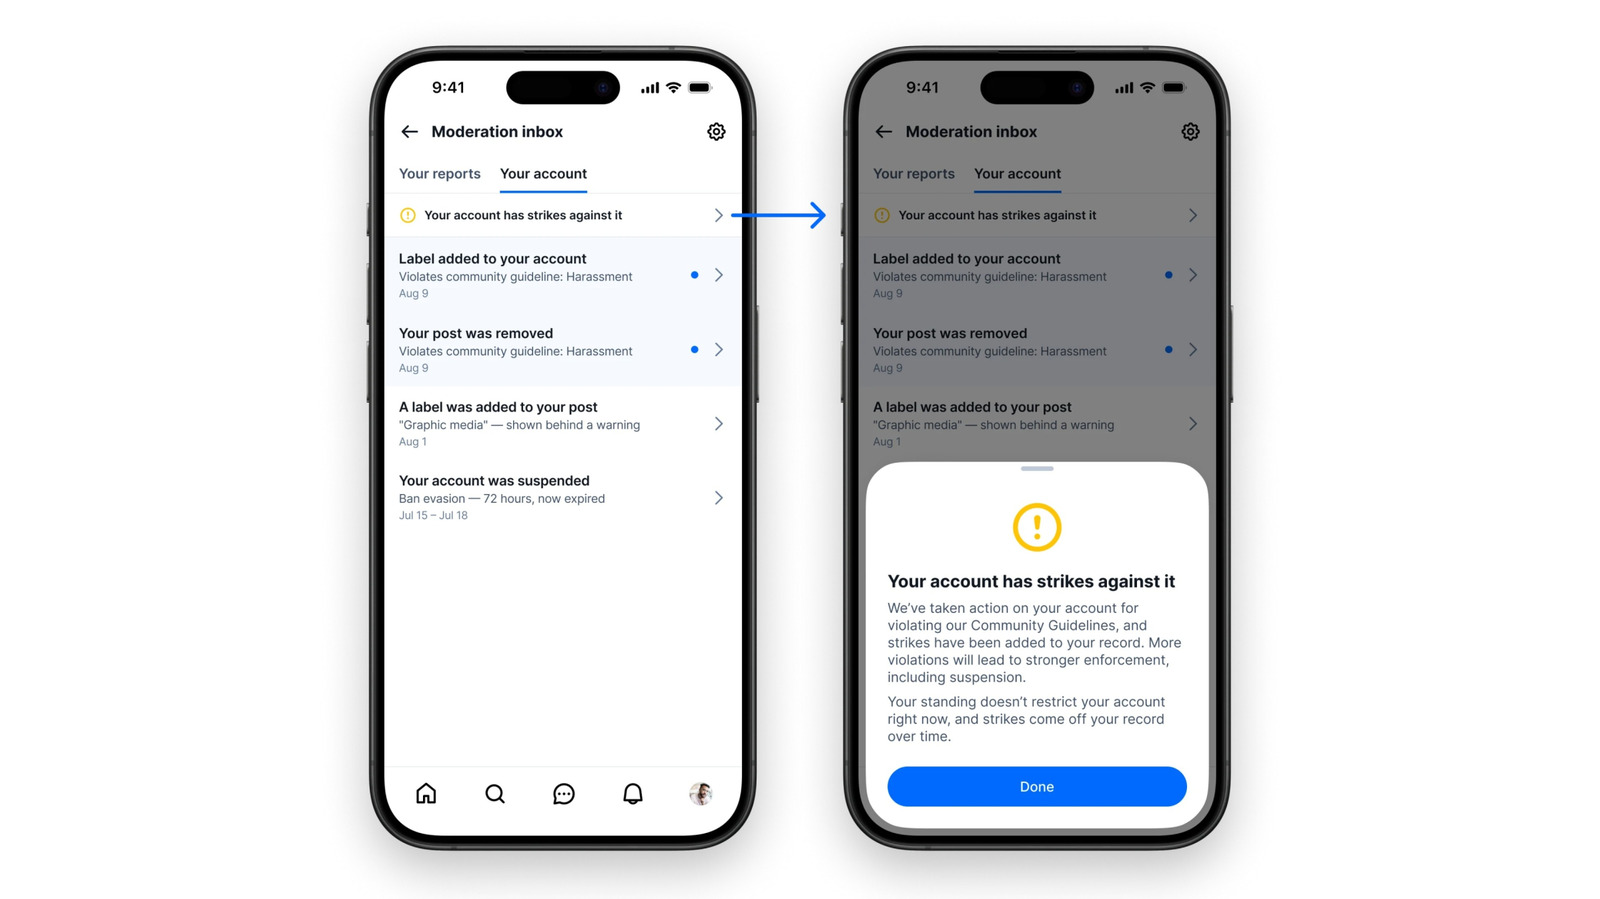
Bluesky Now Has A Dedicated ‘Moderation Inbox’
AI & Technology

Bluesky Now Has A Dedicated ‘Moderation Inbox’

October 30, 2026
Next Post
FM: Why I Am Not A Buyer

FM: Why I Am Not A Buyer

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
What Could a Combination of SpaceX and Tesla Look Like?

What Could a Combination of SpaceX and Tesla Look Like?

October 25, 2026
Full Episode: TODAY Show – Oct. 16

Full Episode: TODAY Show – Oct. 16

October 24, 2026
Amazon earnings live: Q3 earnings miss sends stock lower – Yahoo Finance

Amazon earnings live: Q3 earnings miss sends stock lower – Yahoo Finance

October 29, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!